
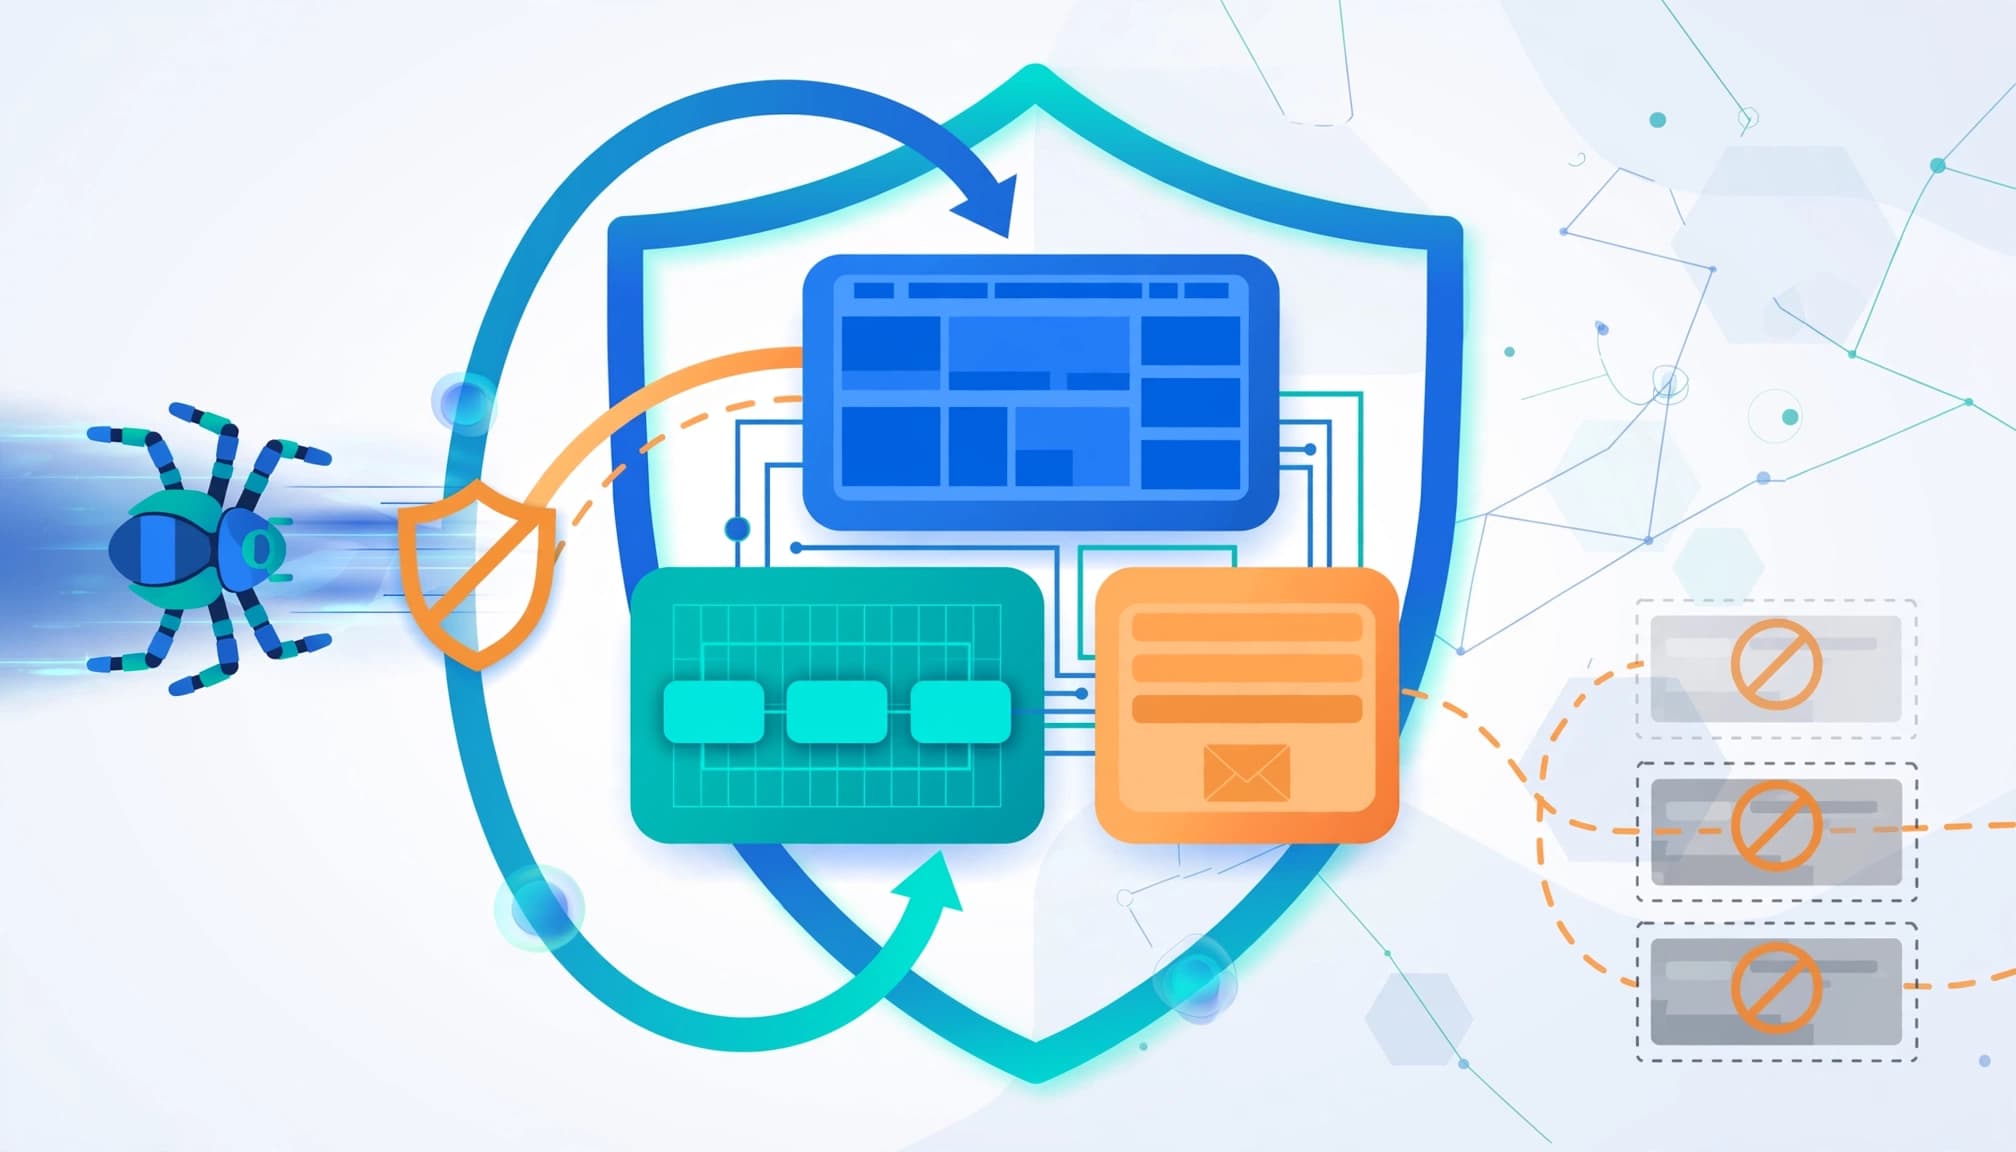
A single misplaced directive can stop search engine crawlers from reaching the page that should bring your next enquiry. For a Kolkata business that depends on service, location, consultation, or quote-request pages, a robots.txt audit protects the routes that support organic lead generation. After validation, your team can request a recrawl for the corrected priority URL, though this doesn’t guarantee immediate indexing.
The robots.txt file has a narrow job, controlling which search engine crawlers may request URLs. It often changes during redesigns, migrations, and CMS updates, so include protocol, host, and subdomain scanning in a broader technical SEO audit, since each host may have its own file. Review rendering, indexing, and conversion checks too. Reducing requests to low-value paths can protect crawl budget and inform an AI readiness score, but it doesn’t guarantee rankings.
Understand Crawling, Indexing, and Lead Value
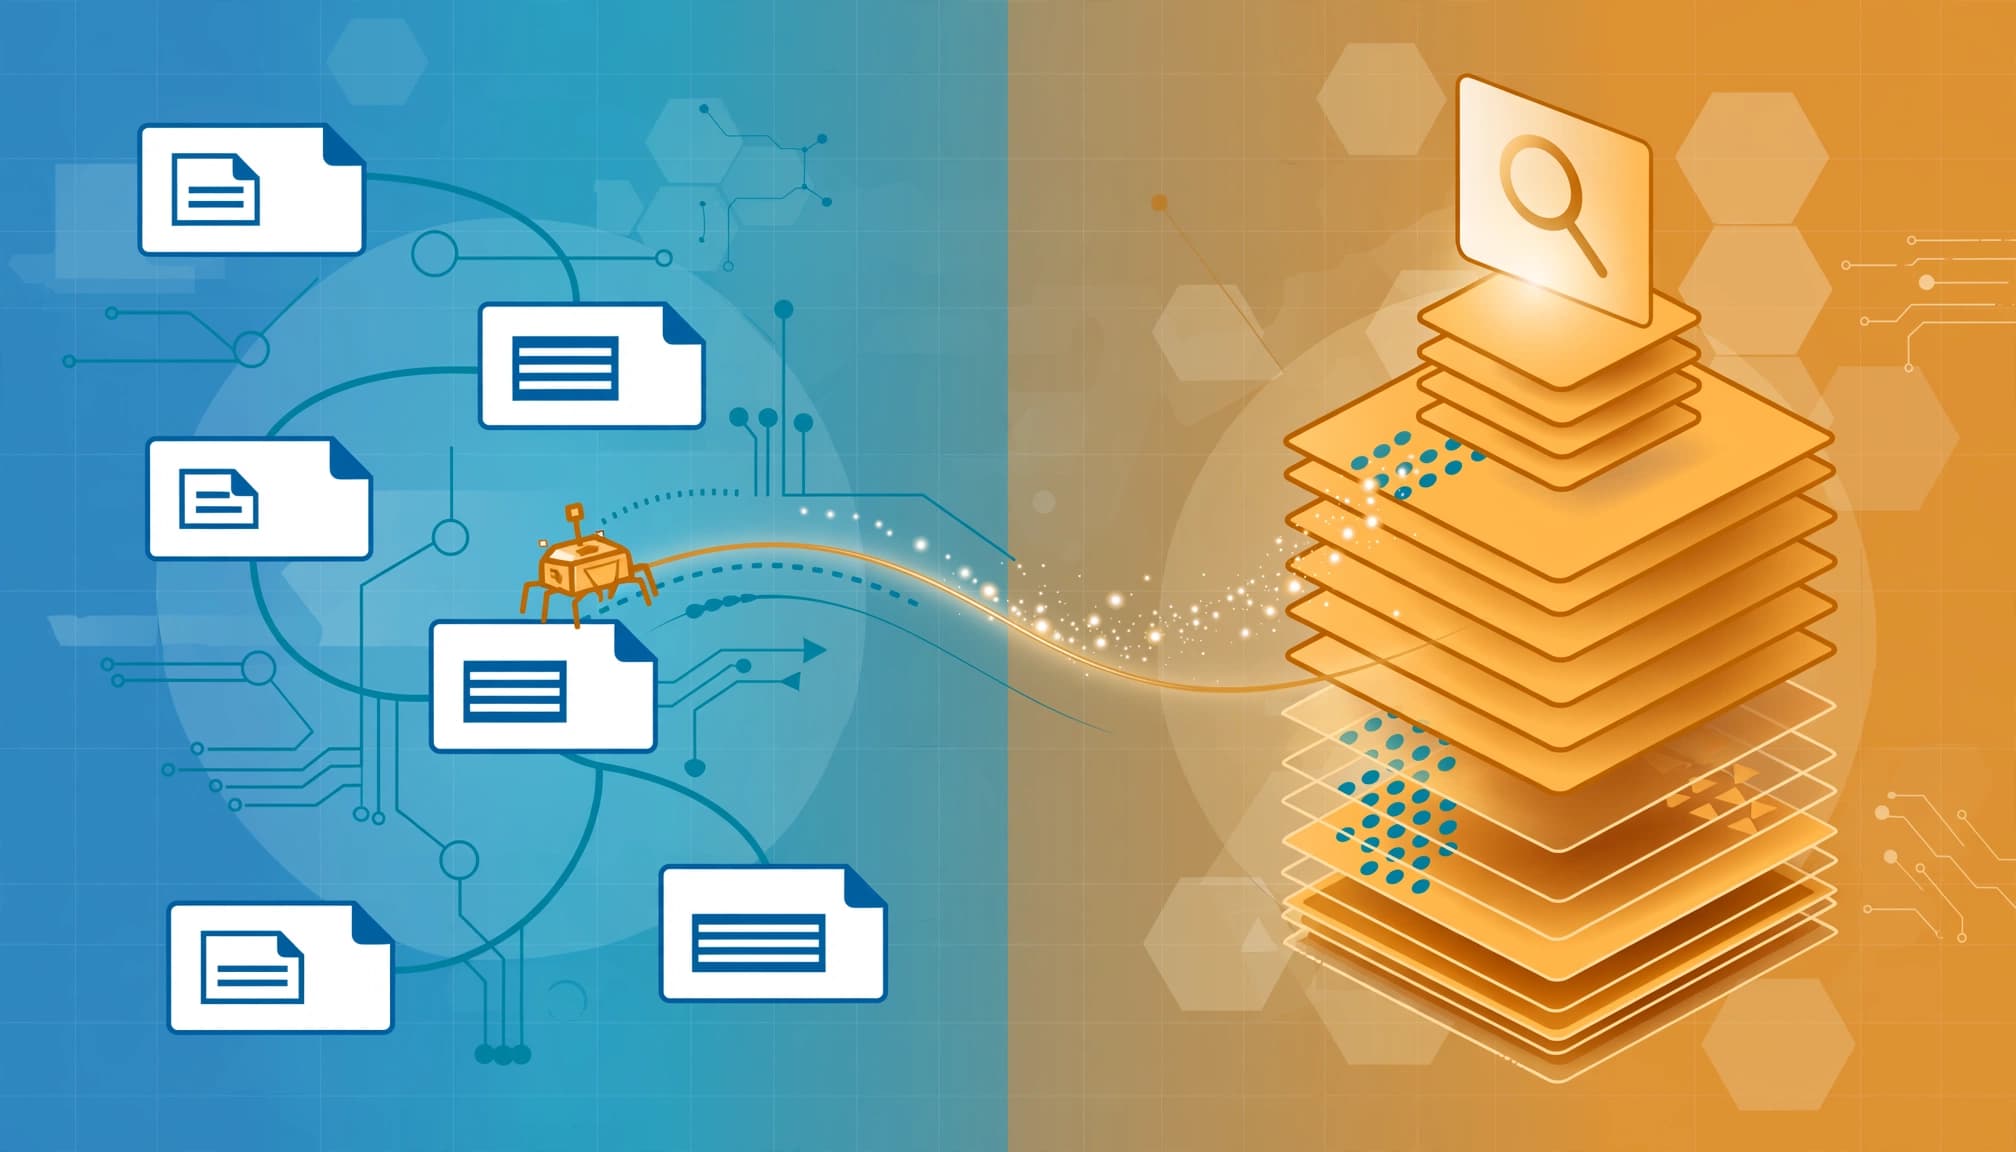
A robots.txt file tells compliant crawlers which URLs they may request. Google explains in its robots.txt introduction that the file mainly manages crawling, including limiting unnecessary requests to a site.
That makes it a useful part of technical SEO. However, crawl access doesn’t decide search indexing, rankings, or qualified leads. Begin every review with a list of pages that matter commercially.
Crawling is not the same as indexing
Crawling means Googlebot fetches a URL and its needed resources. Indexing means Google decides it can store and potentially show that page in search results. Crawl access is a prerequisite for Google to evaluate a page for search indexing, but it isn’t an indexing decision itself.
A URL blocked by robots.txt can still appear in Google and search engine results if another site or internal page exposed it.
Use a noindex meta robots tag or HTTP header when a public page should leave the index. Don’t block that same URL in robots.txt, because Google then may not fetch the directive. Use a 301 redirect for a replacement page, or a 410 response when content has permanently gone. Once the rule, noindex state, or redirect is validated, you can request a recrawl for the affected URL.
Canonical tags handle a different problem. They tell search engines which version of similar pages is preferred. A canonical selects a preferred duplicate, but it isn’t a dependable removal method.
Identify the pages that deserve crawler access
Create a priority inventory before reading directives. Include service pages, industry pages, location pages, pricing pages, case studies, comparison pages, and contact routes. Also record each page’s intended conversion, canonical URL, organic clicks, and verified lead outcome.
An AI readiness score can separately assess crawler access, rendering, and content availability. Treat it as a diagnostic, not a Google ranking metric.
Thank-you pages, login areas, internal search results, duplicate filter pages, staging routes, and test pages usually need different treatment. A lean index can outperform a large one when it contains pages that match real buying intent.
For wider checks across crawlability, conversion paths, and analytics, use this lead generation SEO audit checklist.
Run the Core Robots.txt Audit Checklist
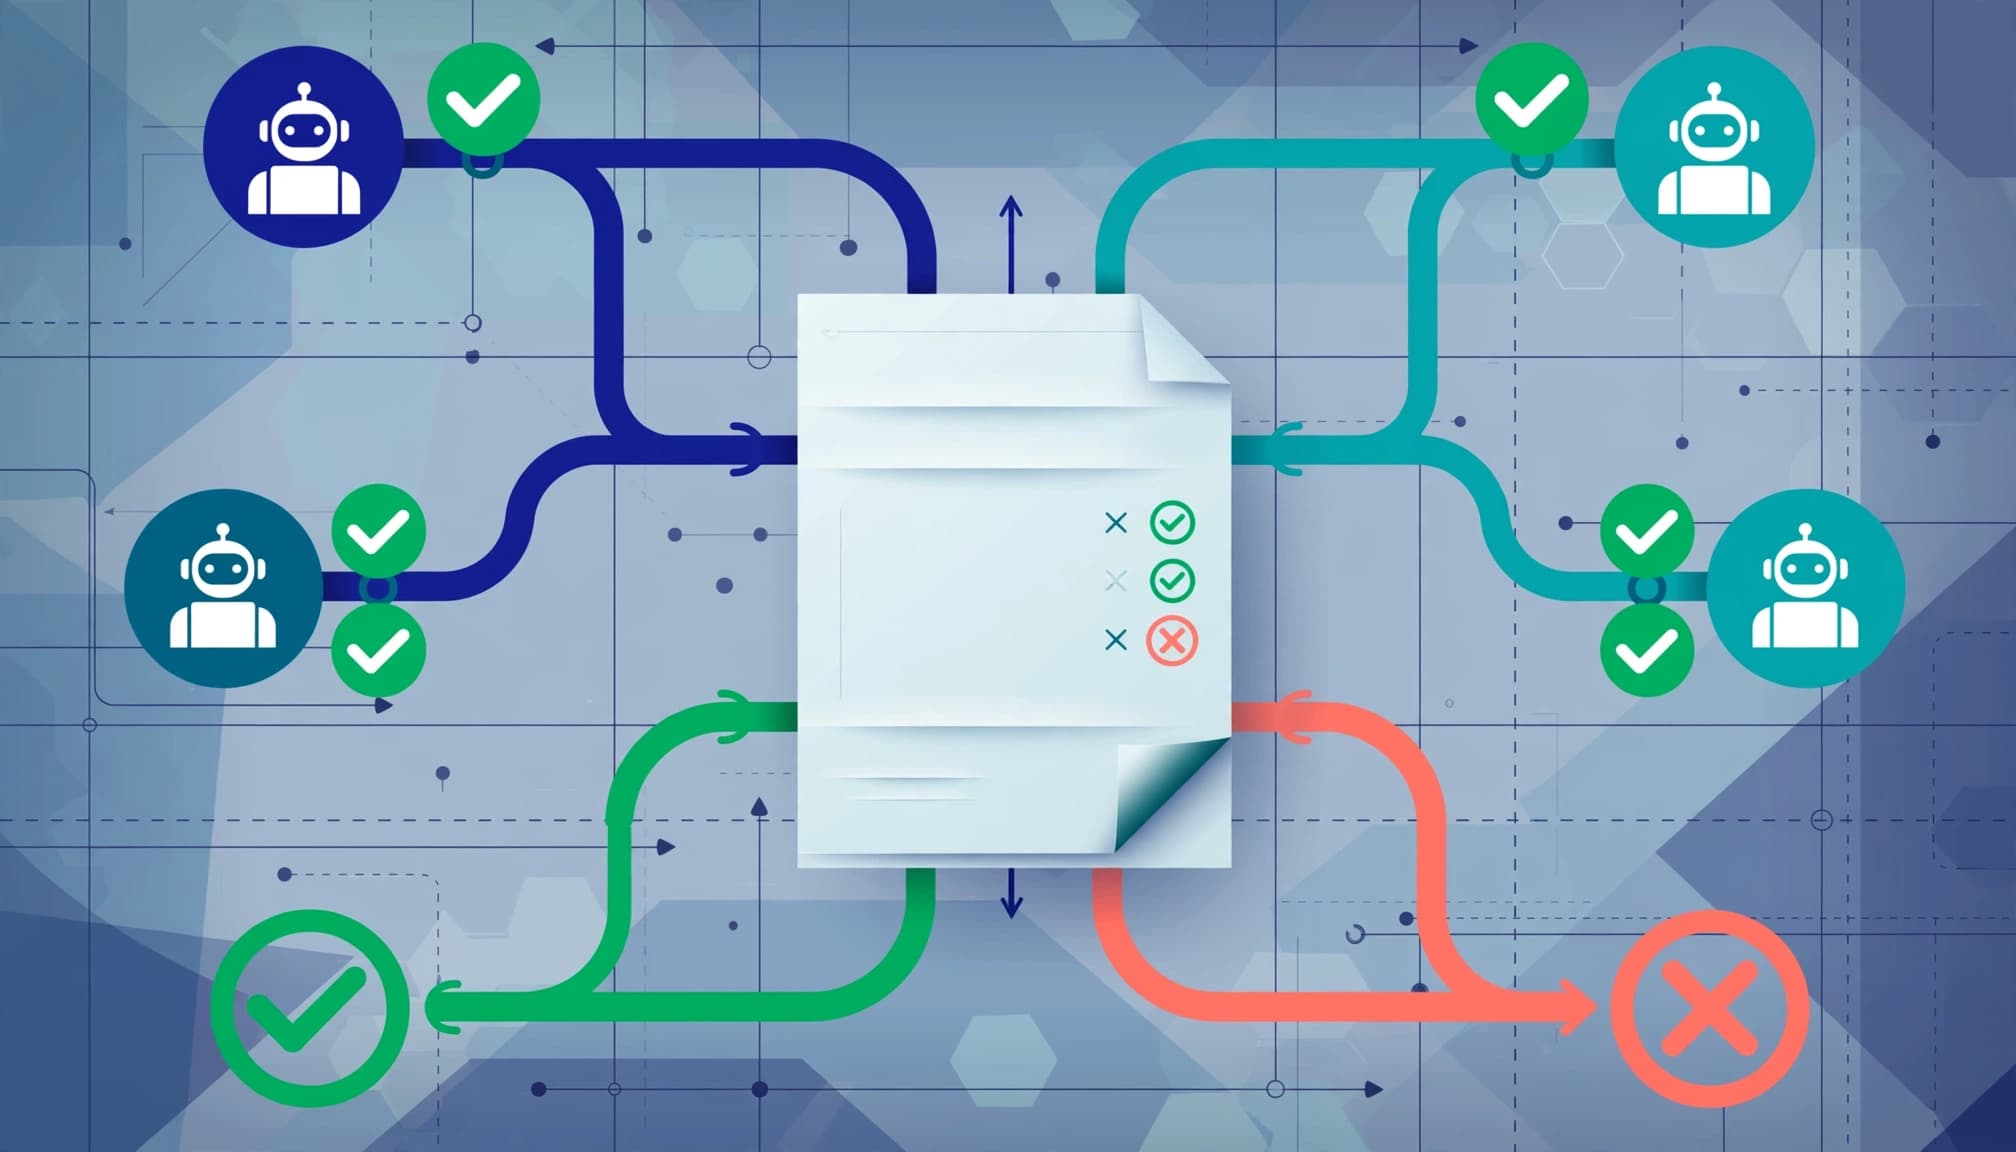
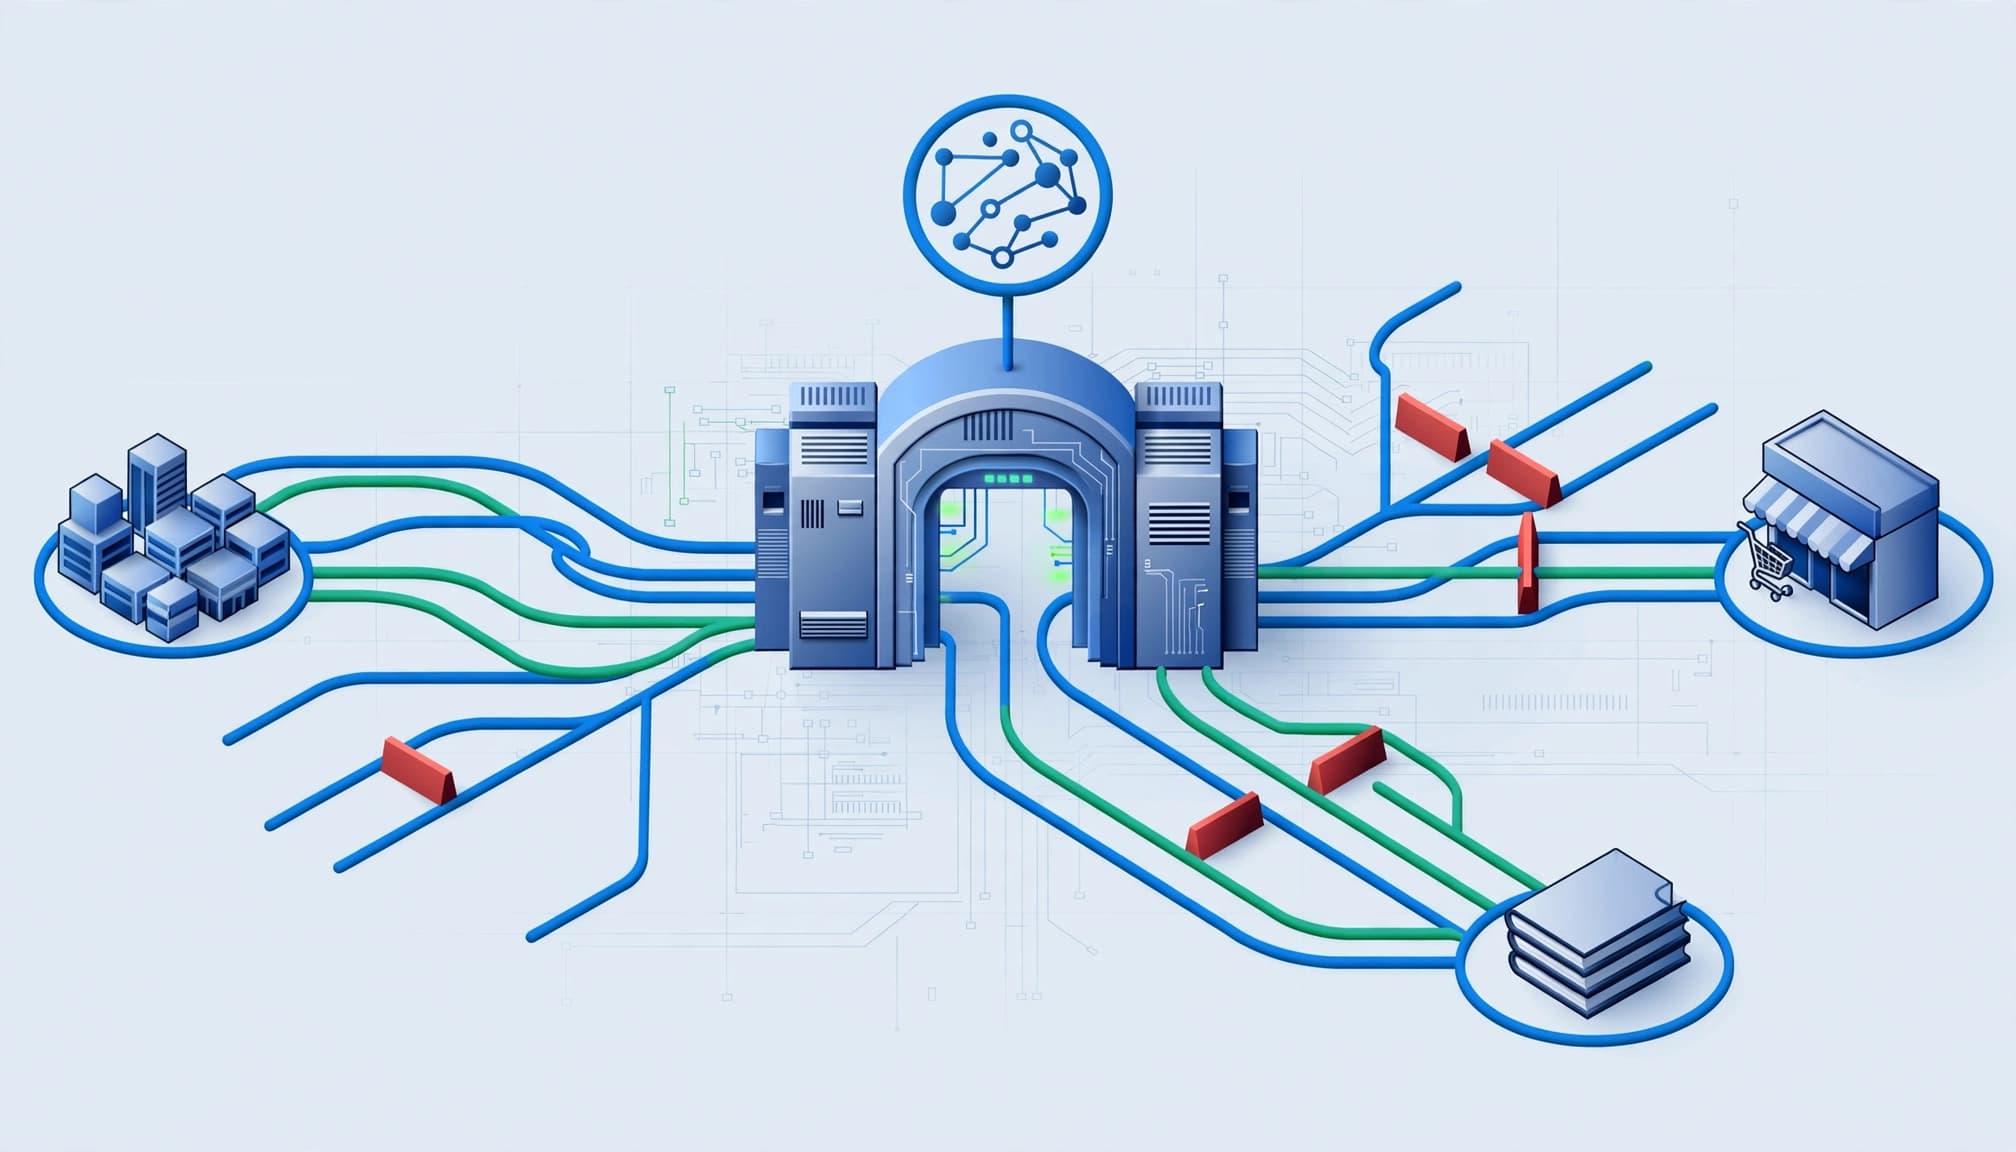
Start with the live file, not a copied version in a developer folder. It must be served from the domain root of the exact host, such as https://example.com/robots.txt. Review HTTP status codes, redirects, and 404 responses.
Each host needs its own review. A file on the www version does not automatically control a non-www host, subdomain, or separate shop. Include subdomain scanning for the public website, blog, help centre, app, and campaign hosts if they can attract search traffic.
Validate user-agent groups and directives
Check every user-agent group, disallow directive, and allow directive. Confirm how each allow directive interacts with a broader disallow rule. Review each user-agent group independently, since copied rules can create unexpected access.
Watch for rules left over from a staging launch, an old CMS, or a security plugin. Perform syntax validation before publishing changes, then use a reputable robots.txt checker as a secondary validation method. Source review, live testing, and crawler documentation remain necessary.
Invalid syntax, misplaced wildcards, and malformed groups can cause parsing issues and unexpected crawler behaviour. Confirm the file follows the Robots Exclusion Protocol in RFC 9309. Keep comments simple, and avoid adding rules until you know which crawler requests you want to reduce.
A blocked lead page may look perfect to visitors while Googlebot cannot fetch it at all.
Robots.txt is not a security tool or access control. Never reveal confidential folders, credentials, customer documents, or private assets through a public file. Protect sensitive material with authentication and proper server access controls to maintain a strong security posture and avoid sensitive path disclosures.
If a blocking rule affects a high-value URL, correct and test it first. Then request a recrawl for that URL, but don’t treat the request as a guarantee.
Check sitemap declarations and response codes
Verify all sitemap declarations in the file, then open the XML sitemap and every child sitemap. Each should return a 200 status and use the current HTTPS domain. Review HTTP status codes, redirects, and 404 responses during this check. A migration can leave an old sitemap URL that now redirects or returns a 404.
Keep only canonical, indexable URLs in the sitemap. Remove redirects, broken pages, parameter variations, noindex thank-you pages, and staging URLs. Sitemap and canonical signals should agree with the pages you want Google to discover.
Verified access, valid responses, and renderable resources can contribute to an AI readiness score. They don’t replace human review of crawl behaviour and business priorities.
Protect Pages That Move Visitors Toward Contact
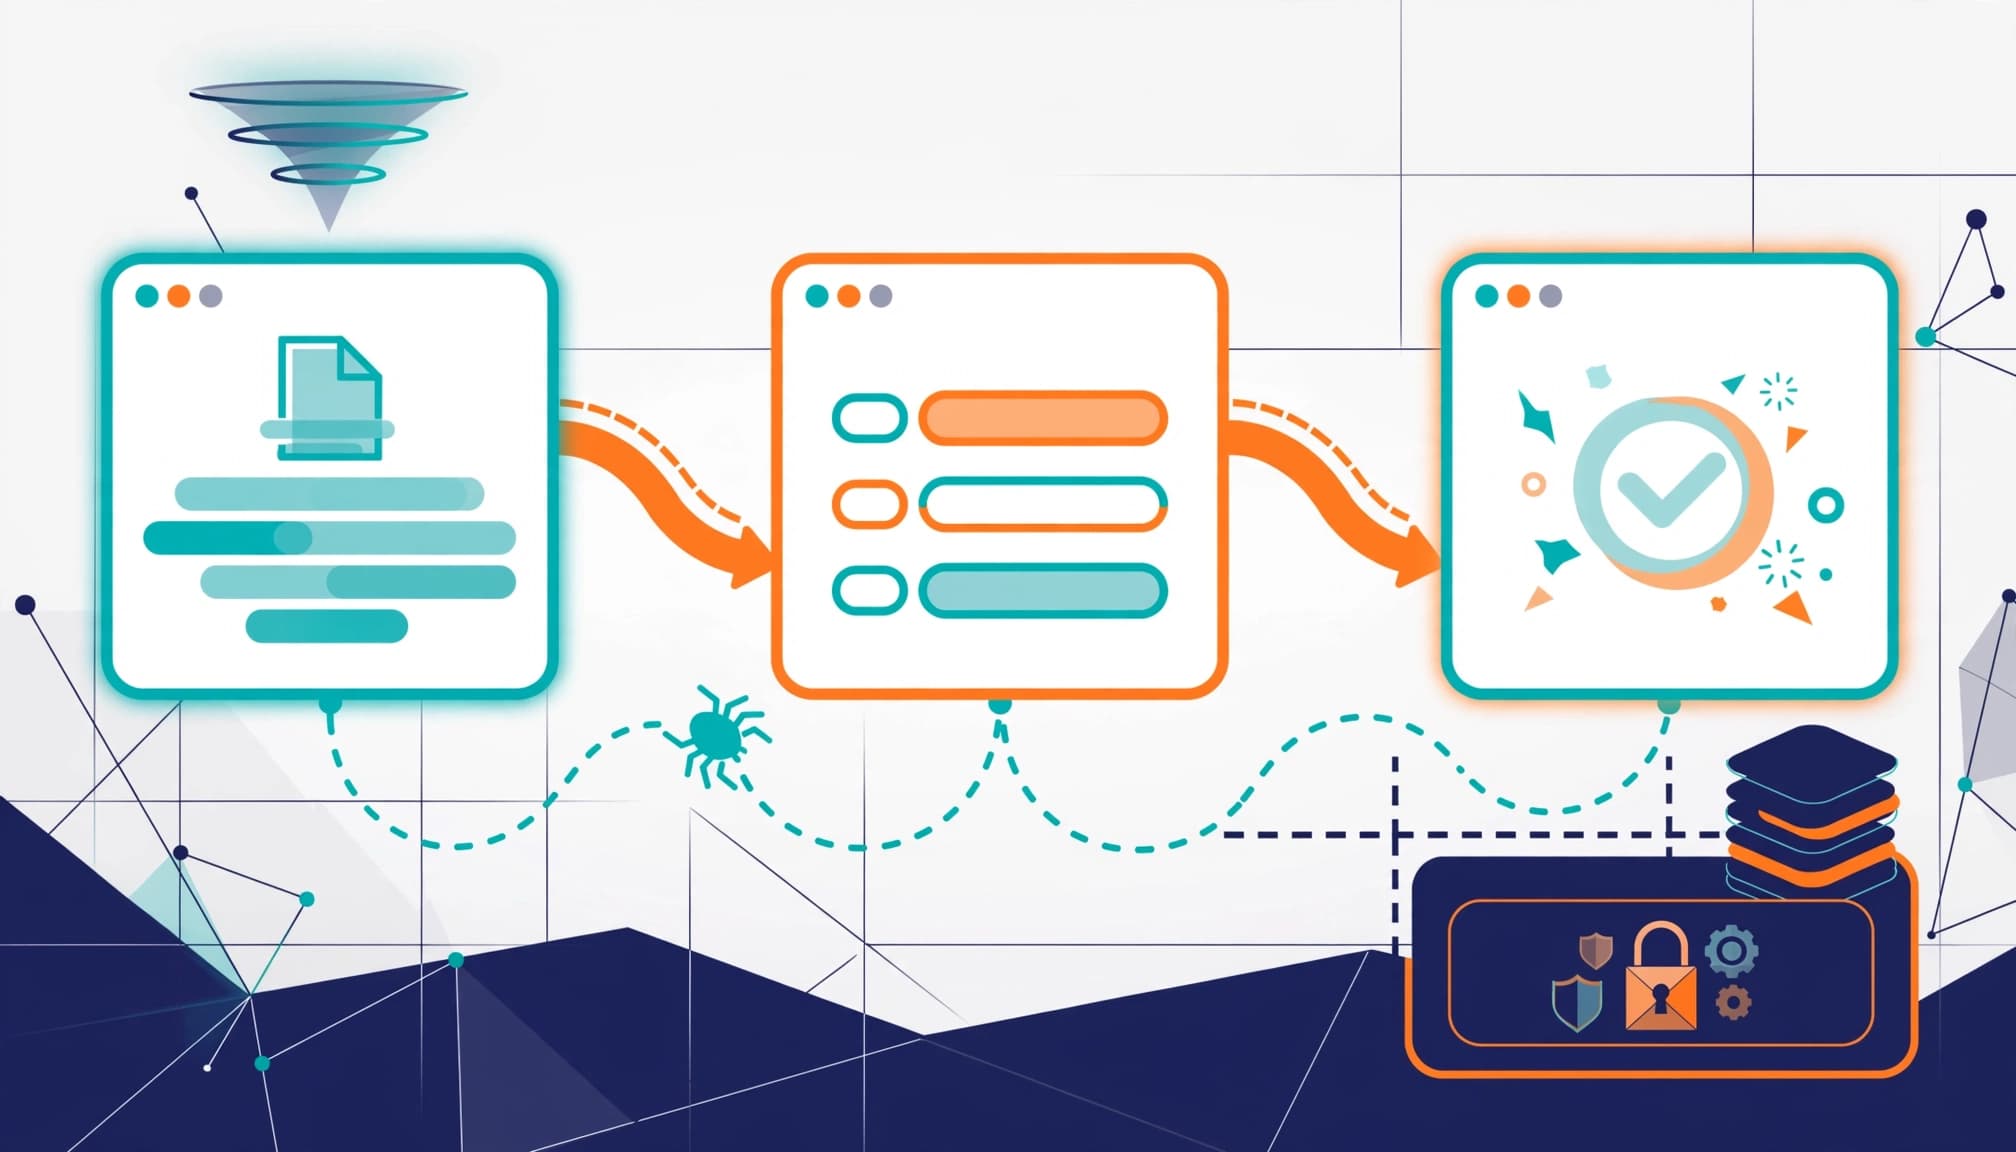
A strong service page cannot produce enquiries if search engines cannot crawl or render it, or if its form fails after landing. Test priority routes as a connected path: search result, landing page, CTA, form submission, and confirmation screen.
Keep the public service, contact, consultation, and supporting proof pages crawlable. Usually, the confirmation page can remain noindexed because it has no independent search value.
Do not block CSS, JavaScript, or form resources
Modern sites often load headings, testimonials, prices, form fields, and internal links through JavaScript. A robots.txt file should not block resources Google needs to render visible content or understand internal links.
Use a browser extension or browser network panel to compare loaded CSS, JavaScript, images, API content, and form resources with what URL Inspection reports. Confirm those findings with a crawl using Screaming Frog or Sitebulb. Incomplete rendering can affect how Google evaluates content for search indexing and lead conversion.
Successful rendering of important content is one input to an AI readiness score, but it doesn’t guarantee AI citations or visibility. Investigate 403 responses, 5xx errors, redirect chains, timeouts, consent walls, and accidental noindex rules.
After making a previously blocked script, stylesheet, API resource, or priority page accessible, test it again and request a recrawl for the affected URL where appropriate.
A JavaScript SEO audit for lead generation sites can help when key content or conversion elements depend on client-side rendering.
Give important pages clear internal routes
Robots.txt cannot repair weak internal linking. Link to money pages from relevant service hubs, location hubs, articles, and case studies with descriptive anchors. A valuable page buried several clicks deep or left orphaned may receive little crawler attention.
Review crawl depth as a tie-breaker when several issues compete for attention. Fix a blocked page that earns enquiries before spending time on harmless tracking URLs.
Set Separate Rules for Search and AI Crawlers
AI crawler decisions now belong in the same audit, but they shouldn’t be mixed with Googlebot rules. Different AI crawlers may have separate identities and purposes. Your policy should reflect business goals, content rights, server capacity, and how each crawler uses retrieved material.
Keep a dated record of every bot-related change. Test Google-facing access rules first, then an owner can request a recrawl for affected Google URLs. This doesn’t force an AI platform to return or guarantee AI search visibility.
Distinguish training from search access
AI platforms may use separate user-agent tokens for model training and search or retrieval. For example, OpenAI distinguishes GPTBot from OAI-SearchBot. Anthropic and Perplexity also use more than one crawler identity.
Blocking GPTBot can limit training data collection without blocking search retrieval. Allowing one token doesn’t grant access to every bot from that company. Review each published token, then decide whether it can access relevant public content.
Treat an AI readiness score as a working rubric
There is no universal AI readiness score that guarantees citations or visibility. A practical internal score can still expose gaps when it measures crawler access, policy clarity, 200-status priority pages, rendering access, useful content, and consistent business information.
Use an AI readiness score as an internal rubric, not a universal ranking or citation metric. Score platforms separately rather than blending every crawler into one number. A clear policy is more useful than a high-looking score that hides blocked service pages or unreliable server responses.
Test, Monitor, and Record Changes
Test after every robots.txt edit, CMS update, template release, security-rule change, or migration. Repeat syntax validation, then check priority URLs instead of assuming the correction worked. After validating a correction to a priority URL, request a recrawl through URL Inspection. Google ultimately re-fetches robots.txt changes on its own schedule.
Use Search Console and crawl checks together
Google Search Console’s robots.txt report shows files Google found for the top 20 hosts, their last crawl dates, and reported warnings. Check it alongside URL Inspection and the Page Indexing report.
Review the live XML sitemap for 200 responses, canonical HTTPS URLs, and no redirects or staging URLs. After manual review and Search Console checks, use a robots.txt checker, but don’t treat automated output as a substitute for testing live URLs.
For site-level patterns, review server responses and Googlebot requests with Google Search Console Crawl Stats. Rising crawl errors can affect priority URLs and require prompt investigation. Compare recurring parsing issues with deployment history and server logs rather than dismissing them as harmless warnings. Repeated access, response, or rendering failures can also lower an internally tracked AI readiness score, though it doesn’t predict rankings or citations.
Maintain a host-by-host change log
Record the date, affected host, directive changed, owner, reason, and validation result. Use subdomain scanning to check the main site, blog, app, and campaign hosts separately.
Run a full review quarterly. Recheck sooner after redesigns, tracking updates, hosting changes, or a sudden fall in impressions on important service pages.
Key Takeaways
- Keep high-value service, location, and contact pages accessible to Googlebot. After correcting blocked URLs, validate them and request a recrawl where appropriate.
- Use
noindex, redirects, or 410 responses for removal goals, not robots.txt alone. - Check each protocol, subdomain, sitemap, and priority URL separately.
- Leave required CSS, JavaScript, and form resources available for rendering.
- Record an AI readiness score as an internal diagnostic. Evaluate platforms separately, and never treat it as proof of search or AI visibility.
FAQ
What is the primary purpose of robots.txt? It guides compliant crawlers away from areas you don’t want them to request, often to reduce unnecessary crawling. It doesn’t secure private content or guarantee removal from search results.
Where should the robots.txt file sit? Put it at the domain root of the exact host, such as https://example.com/robots.txt. Review separate files for subdomains and alternate hosts. Subdomain scanning is also needed when blogs, apps, campaign hosts, or help centres can attract search traffic.
How often should a lead-generation website audit robots.txt? Check it quarterly and after any website launch, migration, plugin change, template update, tracking deployment, or security configuration change.
Can I block a page that already appears in Google? Blocking it may stop Google from seeing a future noindex directive. Keep crawling available so Google can read the meta robots tag, then use noindex, a relevant redirect, or a 410 response based on the page’s purpose. After correcting the issue, you can request a recrawl for the affected URL, but this doesn’t guarantee immediate removal or indexing.
Keep Crawl Access Tied to Business Goals
A good robots.txt file does not try to control every URL. It keeps unnecessary paths out of the crawl queue while leaving your most useful pages easy to fetch, render, and understand.
Review robots.txt audit findings alongside indexing, page quality, form tracking, and CRM outcomes. Crawl access, rendering, and response reliability may contribute to an AI readiness score, but business goals and real lead outcomes remain the priority. If an important page is blocked or broken, Get In Touch With Us to diagnose the issue before it costs more qualified enquiries. After fixing and validating the page, request a recrawl for the URL, then monitor impressions and leads. Clear crawler policies can support AI search visibility, but they can’t guarantee citations, rankings, or enquiries.