SEO Crawl Waste: Analyze Server Logs on Large Websites

SEO crawl waste
Crawler attention on priority pages

Googlebot can visit your website frequently while valuable pages remain undiscovered, limiting organic visibility. On large catalogs and publishing sites, wasted crawling can hide behind healthy-looking request totals.

Server logs reveal where verified crawlers spend their time, but you need to connect those requests with business-critical pages. Start by separating necessary crawling from avoidable URL duplication, then measure whether your fixes improve discovery.

Key Takeaways

  • Crawl waste is avoidable crawler activity on low-value URLs—not every redirect, excluded page, or resource. More requests don’t guarantee indexing or rankings.
  • Use complete server access logs and verify Googlebot by source IP or reverse DNS before measuring requests. Preserve URL variants, and keep CDN and origin data from being counted twice.
  • Segment verified requests by URL type and compare crawl patterns with sitemaps, site inventory, and business-critical pages. Prioritize URL groups that consume requests while important pages receive little attention.
  • Fix underlying patterns safely: update internal links and sitemaps, consolidate redirects, address server errors, and restrict unwanted URL combinations only after checking their purpose. Canonicals and noindex directives don’t immediately prevent crawling.
  • After deployment, compare equivalent log periods and track unnecessary requests alongside priority-page coverage, response times, and business outcomes. Lower crawl totals alone don’t prove improvement.

What SEO crawl waste means on large websites
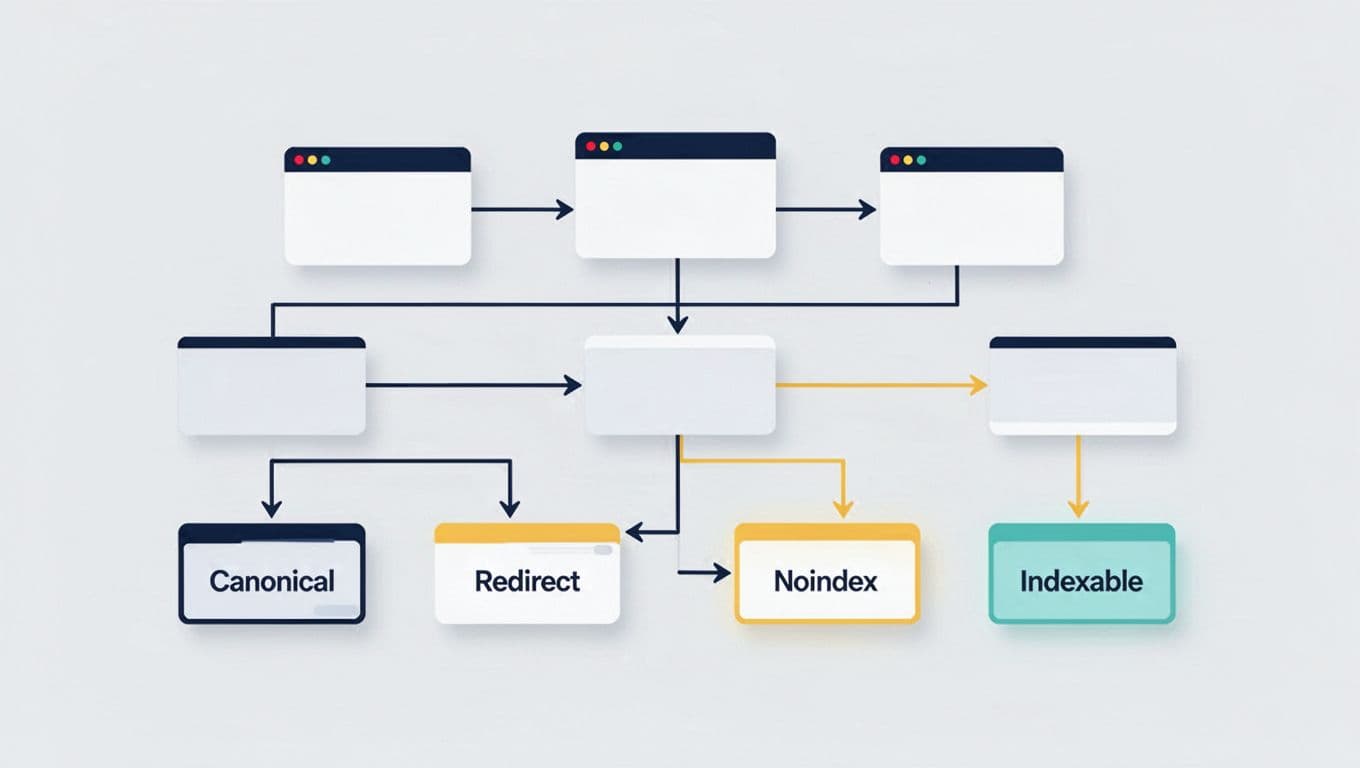
Priority pages and duplicate branches

Crawl waste is avoidable crawler activity on URLs that add little value to search discovery, reducing crawl efficiency. However, redirects, excluded pages, and resources aren’t automatically wasteful. Google sometimes needs to revisit them.

Crawl capacity and crawl demand differ
Crawl capacity and demand

The crawl capacity limit controls how quickly Google can fetch URLs without overloading your server. Slow responses and availability problems can restrict this limit.

Meanwhile, crawl demand reflects Google’s interest in your URLs, including popularity, freshness, and perceived inventory. Faster hosting doesn’t guarantee more demand.

Crawl budget reflects both the crawl capacity limit and crawl demand, rather than a fixed daily allowance. Google’s crawling and indexing documentation also separates fetching content from deciding whether to index it. More requests don’t guarantee rankings.

Large catalogs multiply the problem
Catalogs with redundant page variants

Filters, sorting options, archives, and location templates can create far more URLs than your main inventory suggests. Enterprise e-commerce sites and frequently updated publishers therefore need closer monitoring of their site architecture and crawl rate limit.

For a Kolkata business, website complexity matters more than company size. A modest team managing a large product catalog can face substantial crawl inefficiency.

However, a small service website with prompt indexing usually needs content and internal-link improvements before extensive crawl-budget work.

Prepare reliable server log data
Server access-log monitoring

Ask your developer or hosting provider for HTTP access data from server log files, not just application error logs. Document which hosts, systems, and dates each export covers, along with the XML sitemaps used for comparison.

Collect complete access logs
Log collection and retention

Start with 28 days as a practical baseline, extending it for seasonal sites or infrequently crawled sections. Keep complete records rather than an unexplained sample.

Capture timestamps, requested host and path, query strings, status codes, user agents, and source IPs. Add response bytes and request duration where available.

If a CDN serves cached pages, origin logs alone can miss requests. Collect edge logs too, but avoid counting the same request twice. Also confirm that proxy headers preserve the genuine client IP through trusted infrastructure.

Normalize without hiding URL variants
Request records grouped for analysis

Align timestamps to one timezone while preserving the original requested URL. Create separate fields for host, path, parameter names, and page template.

Keep query strings during investigation. Parameterized URLs can create thousands of filter combinations that look like one harmless category URL when collapsed.

Similarly, avoid lowercasing paths unless your platform treats case variants identically. Protect access to raw logs because IPs and query strings can contain sensitive information. Use sanitized exports for broader team reporting.

Verify Googlebot before measuring requests
Crawler source verification

A user-agent containing “Googlebot” identifies only candidate Googlebot crawl requests. Anyone can send that label, so counting requests without verification can distort your findings.

Validate source IPs against Google’s published crawler ranges, or use reverse DNS verification. Check the returned hostname against Google’s documented domains, then resolve it forward. It must resolve back to the original IP.

Cache verification results by IP and refresh them periodically, rather than repeating lookups for every request. Record unmatched requests separately instead of silently accepting them.

Next, distinguish Googlebot Smartphone and Desktop from AdsBot and other Google crawlers. Their purposes differ, so combining them can obscure search-crawl patterns.

For technical SEO analysis, Screaming Frog Log File Analyser can support request analysis. For very large exports, aggregate records in a database or warehouse using SQL, while retaining URL-level drill-down.

Segment requests and calculate crawl efficiency
Requests separated into URL groups

Classify HTML requests into products, categories, approved facets, unwanted combinations, articles, and utility pages. Keep images, scripts, and stylesheets separate because necessary rendering resources shouldn’t inflate your waste estimate.

Then join requested URLs with CMS inventory, sitemap exports, and a Screaming Frog SEO Spider or Sitebulb crawl. Add crawl depth, canonicals, indexability, internal-link counts, and business priority.

Use these measures together:

MeasureCalculationPractical use
Low-value request shareLow-value HTML requests divided by all verified HTML requestsShows where avoidable crawling concentrates
Priority-page coveragePriority URLs fetched divided by priority inventoryReveals important pages absent from the observed requests
Repeat intensityRequests divided by unique URLs within a segmentHighlights heavily revisited groups
Error shareFailed requests divided by verified requestsTracks access problems

Together, these measures help diagnose crawl efficiency, but they aren’t universal targets. Necessary checks of removed or excluded URLs can occur within apparently inefficient segments.

Cross-check trends with the Crawl Stats interpretation guide. Google Search Console provides broader patterns, while logs supply request-level evidence.

Also remember that missing log activity proves only that no request appears in your captured window. It doesn’t prove Google has never discovered that URL.

Diagnose the biggest sources of SEO crawl waste
URL routing and crawl controls

Rank URL groups by request volume, unique URL growth, and their relationship to neglected priority pages. Prioritize low-value URLs that divert requests from important pages. Fix patterns to improve crawl efficiency instead of repeatedly repairing individual URLs.

Facets and programmatic page sprawl
Filters multiplying ecommerce URLs

Group parameterized URLs by parameter names and combinations. Sorting, session identifiers, and overlapping filters can create near-identical listings through faceted navigation.

Approved facets may answer genuine search demand, so evaluate their inventory and unique value before restricting them. Duplicate content or index bloat can signal issues, but don’t automatically prove a URL group should be blocked. Google’s URL structure guidance addresses URL complexity and faceted navigation.

For programmatic SEO, compare generated templates against meaningful differences in content. Location or category permutations shouldn’t expand indefinitely without a clear purpose.

Finally, inspect empty-result combinations. An empty-result page returning 200 needs review for soft 404 errors; a parameter alone doesn’t establish a crawl trap.

Redirects, errors, and JavaScript dependencies
Redirect and rendering problems

Repeated 3xx requests can reveal outdated internal links or sitemap entries. Confirm redirect chains with a crawler because logs don’t always record each destination.

Investigate persistent 5xx errors and rising response times first. A 200 response doesn’t guarantee useful content, and soft 404 errors can hide behind successful HTTP responses.

Rendering-resource requests aren’t inherently wasted. However, broken scripts or inaccessible dependencies can obstruct important content. A JavaScript SEO audit helps compare raw HTML, rendered links, and route accessibility on framework-based websites.

Prioritize fixes by business risk
Business-focused repair priorities

For crawl budget optimization, repair inaccessible revenue pages and server instability first. Address slow server response times before chasing a cleaner percentage. Then fix high-volume URL patterns that consume unnecessary requests and have a safe template-level solution.

Give each issue an owner, affected templates, deployment date, and acceptance test as part of technical SEO implementation. Developers own server and routing changes; SEO teams define preferred URLs and discovery rules.

Match the control to the problem:

  • Update internal links and XML sitemaps to point directly to preferred, indexable URLs returning 200.
  • Consolidate redirect chains, and return appropriate 404 or 410 responses for genuinely removed content.
  • Restrict unwanted crawlable combinations only after checking approved facets and important resources.

Canonical tags indicate a preferred URL, but they don’t immediately prevent crawling. Noindex meta tags require Google to fetch the directive, so they don’t immediately save crawl requests.

Blocking an indexed URL in the robots.txt file can prevent Google from seeing its noindex directive. Decide whether you need crawl prevention or index removal before deploying either control.

Follow Google’s robots meta tag specifications when excluding accessible pages. Test both blocked and permitted URLs before releasing robots.txt changes.

Also improve discovery through internal linking. Important orphan pages need relevant links; robots.txt changes can’t create those routes.

Validate improvements after deployment
Before-and-after crawl monitoring

Re-crawl changed templates immediately to check responses, canonicals, directives, and rendered links. Google’s SEO guide for developers provides practical accessibility checks.

Then compare equivalent log periods using the same hosts, bot verification, and URL classifications. Allow time for Google to revisit affected sections, and account for promotions, publishing changes, and outages.

Look for fewer unnecessary requests alongside stable or improving priority-page coverage, which can improve crawl efficiency without sacrificing organic visibility. Also compare response times and failed requests. Measure indexation speed by tracking how quickly newly published priority URLs receive their first observed fetch.

In Google Search Console, review host status and request trends before investigating specific URLs. Check the Page Indexing report and URL inspection tool for indexing outcomes.

Maintain a dated change log so shifts can be traced to releases. Automate daily segment summaries and alerts for unusual error rates or sudden growth in unwanted URL groups.

Finally, connect repaired landing pages with GA4 sales or CRM-qualified enquiries. Lower crawl totals alone don’t establish business improvement.

Frequently asked questions
Crawl analysis questions

Can Search Console replace server logs?

No. Crawl Stats helps identify response, resource, and host-level trends, but it isn’t a complete URL-by-URL request history. Use logs to investigate individual paths and parameter combinations.

Does “Crawled, currently not indexed” prove crawl waste?

That status confirms Google crawled the page but hasn’t indexed it. It doesn’t identify one technical cause. Review content value, duplication, canonicals, and internal links before restricting access.

Should every non-indexable URL be blocked?

No. Google may need access to read noindex directives, follow redirects, or process rendering resources. Apply a documented URL policy rather than blocking every excluded page.

Make crawler attention useful to your business
Clear routes to important pages

Reliable log analysis connects verified crawler activity with the business-critical pages that support organic visibility. Better priority-page access matters more than a higher or lower crawl total.

If your catalog or content archive needs a coordinated technical review, Get In Touch With Us to connect crawl findings with practical fixes and measurable outcomes.

Faceted Navigation SEO: Control Filter URLs and Crawl Paths

Product cards and filters connect to selected collection paths, while excess routes fade behind a barrier.

Your product filters can create more URLs than your store has products. Effective faceted navigation SEO keeps browsing useful while preventing unnecessary URLs from competing with important collections.

For Kolkata retailers, page purpose and search intent should determine which filters on ecommerce sites deserve search landing pages. That applies whether you sell sarees, footwear, or home furnishings. Crawl blocking, indexation directives, and canonical tags solve different problems.

Start by separating shopper choices from the search destinations that support your ecommerce SEO strategy.

How Product Filters Multiply Crawl Paths

Blue and amber category paths branch among product and parcel silhouettes.

Faceted navigation, or faceted search, lets shoppers narrow a catalog using product attributes such as size, colour, material, brand, and price. Each selection can generate another URL.

Combinations of those attributes, sorting, pagination, repeated parameters, and different selection orders create many crawlable URL variations. Two URLs may show identical products despite using different parameter sequences.

These patterns create two issues. Search engine bots may spend crawl budget exploring low-value combinations, while Google discovers near-identical pages that contribute to index bloat.

Duplicate content doesn’t automatically trigger a penalty. Still, competing URL versions can complicate canonical selection and scatter internal links across unnecessary destinations.

Google’s faceted-navigation crawl guidance recommends preventing unnecessary filtered URLs from being crawled. But blocking every filter indiscriminately can also hide useful landing pages.

The goal is a controlled architecture: stable category and product URLs, selected searchable collections, and shopper-only filter states.

A category shelf branches into a few neatly organized collections.

Build a Faceted Navigation SEO Allowlist

Orange tiles cluster at the center of a grid as colored tiles fade toward the edges.

Default to shopper-only filters, then approve combinations with a clear search purpose. An allowlist is easier to govern than reviewing millions of generated URLs individually.

Prioritize Demand and a Useful Product Selection

Footwear, clothing, and home goods arranged in groups with colored pins.

Use Search Console queries, keyword research, and sales data to find long tail keywords and understand search intent. For a saree retailer, fabric-based product attributes may merit consideration when customers search for them.

Demand alone isn’t enough. Each approved destination needs a distinct purpose and a useful, reasonably stable product selection. Faceted search combinations can become stable landing pages when they serve shoppers and support a clear choice.

Price sliders, availability toggles, and arbitrary multi-filter combinations usually remain browsing tools. Assess purpose rather than banning an attribute globally.

Give approved destinations self-referencing canonicals and contextual internal links, concentrating link equity on preferred pages. Include them in XML sitemaps only when they return 200 and are intended for indexing.

Normalize URLs Before They Spread

Green and blue blocks form a neat path, with duplicate pieces set aside.

Define a consistent url structure, with one parameter order and encoding. Remove repeated filter parameters and redundant defaults before templates generate links.

Where equivalent URLs already exist, a relevant permanent redirect can consolidate versions with no separate browsing purpose. Avoid redirect chains.

Keep search approval explicit: approving a material collection shouldn’t automatically approve material, size, and availability combinations.

Document valid attributes, compatible values, and which combinations receive stable landing pages. This limits uncontrolled URL growth without restricting shoppers’ choices.

Choose Canonical, Noindex, Robots.txt, or 404

A pointer, closed book, gate, and empty shelf arranged in a row on white.

Choose a control based on what the filtered URL should do in faceted search.

URL purposeAppropriate controlWhat it accomplishes
Approved search landing pageSelf-referencing canonicalIdentifies the preferred version
Duplicate that remains usefulCanonical to an equivalent pageSignals consolidation
Public page excluded from searchNoindexControls indexation after crawling
Unnecessary crawlable combinationsRobots.txt disallowRestricts crawler access
Invalid or empty filter combinationHTTP 404Reports that no results page exists

Canonical tags are consolidation signals, not crawl blocks. Google’s canonical URL guidance applies to duplicate or very similar pages.

Don’t point every filtered page to its parent category. A distinct product subset may need its own canonical or exclusion policy.

Meanwhile, Google’s noindex guidance requires crawler access. Use a noindex tag or an X-Robots-Tag HTTP header so Google can read the directive.

A robots.txt block can stop Google from reading both a noindex directive and a canonical tag.

Robots.txt controls crawling, not removal from search results. For indexed URLs that need exclusion, allow crawling so Google can process noindex. Don’t add a simultaneous crawl block.

Test disallow rules against actual parameter patterns and approved landing pages. No universal rule safely covers every store.

Return 404 for invalid or empty filter combinations rather than redirecting everything to the main category. However, don’t automatically delete a useful curated collection because inventory temporarily runs out.

Make JavaScript Filtering Crawl-Safe

Product tiles sit inside a browser panel beside a crawler path to a few categories.

AJAX filtering doesn’t automatically prevent crawling. URL generation, rendered links, and server responses determine how faceted search states are discovered.

Check both the initial HTML and the page after JavaScript runs.

Keep Shopper-Only States Out of Navigation Links

A phone with blurred color tiles sits beside neatly arranged products on a shelf.

Buttons and accessible form controls can update products without publishing a crawlable link for every selection. This supports a good user experience while keeping shopper-only states out of navigation. Fragment-based states can also support filtering, and Google generally doesn’t use fragments as separate indexable URLs.

However, changing query parameters through the History API still creates addressable URLs. Those URLs need a server-side policy, even without visible filter links.

React, Vue, and Next.js implementations should apply the same rules to direct requests and client-side navigation. Otherwise, a shared filter URL may return different directives after a refresh.

Preserve keyboard access, back-button behaviour, and shareability where shoppers need them.

Protect Category and Product Discovery

Three groups of miniature products stand out from faint scattered variations on a white surface.

Important destinations need real anchor links with href attributes. Link category pages to products, and don’t make product discovery depend entirely on someone clicking “Load more.”

Provide crawlable pagination or another dependable linked route to every product. Don’t automatically canonicalize every pagination page to page one when each contains different products.

Keep required scripts, styles, and content resources accessible. Google’s JavaScript SEO guidance explains how rendering and HTTP responses affect discovery and indexing.

On Shopify, verify theme and filter-app output rather than assuming native filters settle every issue. Recheck canonicals, links, headers, and direct responses after app or theme changes.

Audit Discovery, Indexation, and Actual Crawling

A magnifying lens rests over a printed site map beside stacked marked reports.

Use this checklist to compare a rendered crawl, sitemap, Search Console data, and server logs. Each source reveals a different part of the problem, but none provides a complete inventory.

Compare Your URL Policy With Search Console

Two similar catalog sheets show overlapping product shapes, with one small difference.
  • Group Page Indexing examples by attribute and template, using faceted search patterns rather than fixing URLs individually.
  • Inspect URL patterns and compare your declared canonical with Google’s selected canonical.
  • Verify directives, HTTP headers, and rendered HTML in the live response.

“Crawled, currently not indexed” confirms a crawl, but it doesn’t identify one specific technical fault. Review page value, duplication, and internal links.

Screaming Frog SEO Spider can compare a connected crawl with sitemap and Search Console URLs. This can expose pages missing from internal navigation and gaps in product discovery.

Measure Where Googlebot Requests Go

A magnifying glass highlights light points beside a server rack as more racks recede into the aisle.
  • Use server log files to segment verified Googlebot HTML requests into products, categories, approved facets, and unwanted combinations.
  • Check response codes, server errors, product discovery, and visits to important pages.
  • Compare request patterns with a baseline, including whether low-value combinations consume crawl budget and create crawl waste.

Look for crawl traps among unwanted patterns, but don’t assume every parameterized URL is one.

Search Console Crawl Stats shows site-level patterns, not a complete URL-by-URL request history. ClickyOwl’s guide to Google Search Console crawl stats explains how to interpret those patterns.

A lower crawl total alone isn’t success. A third-party page-rank score can’t replace evaluating discovery, indexation, traffic, or revenue. Look for fewer unnecessary requests alongside healthy product discovery and stable organic sales.

Put Indexability Rules Into Your Release Process

Cards and product tiles sit in separate piles, connected by a wooden path and brass marker.

Create one shared rule system for faceted navigation rules. SEO defines each page’s purpose, developers implement the technical SEO requirements, and merchandising maintains the product selection.

The system should determine the normalized URL, status code, canonical target, indexation directive, and sitemap eligibility. Navigation templates should follow the same decisions.

Test approved facets, excluded states, reordered parameters, invalid values, empty results, and pagination before deployment. Check direct requests as well as client-side transitions.

Also inspect final responses after redirects. Clean HTML doesn’t rule out a server-level noindex header.

Roll out major changes to one category first. Record the deployment date, then compare crawling, indexing, organic landing-page traffic, and purchase revenue against the baseline.

For smaller stores, a policy spreadsheet and template tests can be enough. Larger catalogs benefit from version-controlled configuration shared across routing, rendering, and sitemap generation.

Give each approved collection an owner and a review date. Stock changes, new filter apps, and theme updates can invalidate earlier assumptions.

Key Takeaways for Store Owners

Wooden branches form a decision tree leading to a miniature open storefront.

Keep the business decision separate from the technical implementation:

  • Approve filtered landing pages when they match customer demand and offer a useful product selection.
  • Use canonicals for equivalent versions, noindex for search exclusion, and robots.txt for crawl restrictions.
  • Validate changes across server responses, rendered navigation, Search Console, and logs.

Judge the outcome by whether valuable collections and products remain discoverable. A smaller index or fewer crawler requests matters only when the store’s useful pages retain visibility.

Frequently Asked Questions

Should every filtered URL be blocked from crawling?

No. Keep approved search landing pages crawlable, and use robots.txt only for unnecessary combinations that shouldn’t be crawled.

Is a canonical tag enough to stop Google crawling a filter URL?

No. Canonical tags signal which equivalent URL is preferred; they don’t block crawling or guarantee indexation. Google must be able to crawl a URL to read its canonical tag.

When should a filtered page be indexable?

Approve it when it matches search demand, serves a distinct purpose, and offers a useful, reasonably stable product selection. Give it a self-referencing canonical and contextual internal links.

How can I tell whether faceted navigation changes are working?

Compare server logs, Search Console data, and rendered crawls to see whether unnecessary requests decline while product discovery remains healthy. Also monitor organic landing-page traffic and purchase revenue against a baseline.

Conclusion: Keep Useful Filters, Control Their URLs

A tidy shop display with orderly shelves and a clear path through the doorway.

Your filters can stay useful without turning every selection into a search landing page. A clear URL policy protects valuable collections and limits unnecessary crawl paths.

Start with one category, verify the controls, then carry the tested rules into future releases. Keep crawl management and indexation control separate.

If filters, theme settings, and server directives conflict, Get In Touch With Us for help identifying the source before changing more templates.

Redirect Chain Audit Checklist for Lead Generation Websites

Connected browser windows lead to a contact form, with one broken link highlighted beside a laptop.

A visitor clicks a service-page link, waits through several redirects, and lands on the wrong form. You may lose the enquiry without seeing an obvious website error. A redirect chain audit can uncover that broken path before it costs you leads.

For a lead-generation website, the work goes beyond counting redirects. Check where visitors land, whether the form works, and whether campaign tracking survives the journey. Start with the URLs that bring people to your business.

Key Takeaways

  • Build a redirect-audit inventory from current, historical, and campaign URLs; preserve query parameters and record each URL’s source and lead value.
  • Trace every URL through all redirect hops, checking status codes, loops, final destinations, and whether the landing page matches the visitor’s intent.
  • Prioritize broken lead paths, high-traffic pages, and campaign URLs that lose tracking—not hop count alone.
  • Fix lasting URL moves with direct redirects to the closest relevant page, and update internal links, CTAs, canonical URLs, and sitemaps.
  • Retest the full journey after repairs: confirm forms and other enquiry actions work, leads reach the CRM, and analytics and campaign attribution are recorded correctly.

Why redirect chains matter on lead-generation websites

Three blue and amber gateways curve toward a landing page with a small form icon.

A redirect chain occurs when one URL sends a visitor to another, which redirects again before reaching the destination. These paths often develop during a site migration, an HTTP-to-HTTPS move, or repeated service-page URL changes.

Each hop adds a request, which may slow the journey and use crawl budget, though redirects alone don’t prove a ranking problem. A redirect loop sends visitors between URLs repeatedly, preventing them from reaching the landing page. These issues are part of technical SEO. Use Google Search Console crawl stats to check whether Googlebot is encountering redirects or errors; Semrush can also flag redirect paths. Validate the HTTP status and test the lead journey, since a status code won’t confirm the right form loads.

For a Kolkata service business, the lead risk is immediate: an old Google Business Profile link might still open, yet send someone searching for one service to a general page with a different enquiry form. The URL resolves, but the visitor’s original intent is lost.

Build a complete URL inventory before the crawl

Paper cards branch into organic, paid, and referral source groups on a bright table.

A current-site crawl shows what your website links to today, including its internal links. It won’t necessarily find an old campaign URL in an email, backlink, or business listing. Collect current, historical, and campaign entry points before testing redirect paths.

Gather URLs beyond the current sitemap

Blank folders, a sitemap diagram, and analytics sheets sit on a table before rows of shelves.

Pull current URLs from your XML sitemap, Google Search Console, and GA4 landing-page reports. Check sitemap entries for outdated URLs and compare them with known active pages missing from the file. Record which sitemap file supplied each URL. Use Semrush to help discover URLs from backlinks.

Add historical URLs from old migration maps, plus destination URLs from Google Ads, email campaigns, QR codes, and social profiles. Include both www and non-www versions where they were used, along with HTTP URLs people may still visit.

Pay attention to service, location, pricing, consultation, and contact pages. A retired landing page with no current internal links can still receive paid clicks or bookmarked visits. Record these URLs even if a normal crawl never discovers them.

Tag lead value and campaign source

A landing page card connects three channel markers to a small form icon.

Give each source URL a row in one sheet. Record its source channel, expected landing page, enquiry action, current traffic, and any known enquiries. Note whether the page should contain a form, phone number, or booking link to support your technical SEO checks.

Keep the full campaign URL, including query parameters. If an ad link carries UTM parameters or Google Ads click identifiers, test whether they survive the redirect. Also flag URLs leading to a hosted form or scheduler, since the conversion may happen on another domain.

Trace every redirect path, including all hops

A cyan route links three server nodes to a final point.

Test the URLs you collected, not just those on the live site, to uncover redirect chains. For every source URL, capture each HTTP status code, every intermediate URL, the final destination, and whether that destination loads successfully.

Configure Screaming Frog for a redirect audit

A monitor with a blurred crawl graph sits beside a printed URL map near a sunny window.

In Screaming Frog SEO Spider, crawl the live site to find internal links that still point to redirects. Then use List Mode to test old and campaign URLs in your inventory. The SEO Spider configuration guidance explains how List Mode can follow redirects to the final target, regardless of crawl depth. Compare those results with Semrush as a second crawl check.

Export the Screaming Frog results and keep the starting URL beside every path. During a site migration, compare each path with the approved old-to-new URL map. Test a sample on mobile as well, particularly if ads or QR codes send most visitors there. This technical SEO check can also reveal redirect issues that affect visitors.

Check status codes, final destinations, and loops

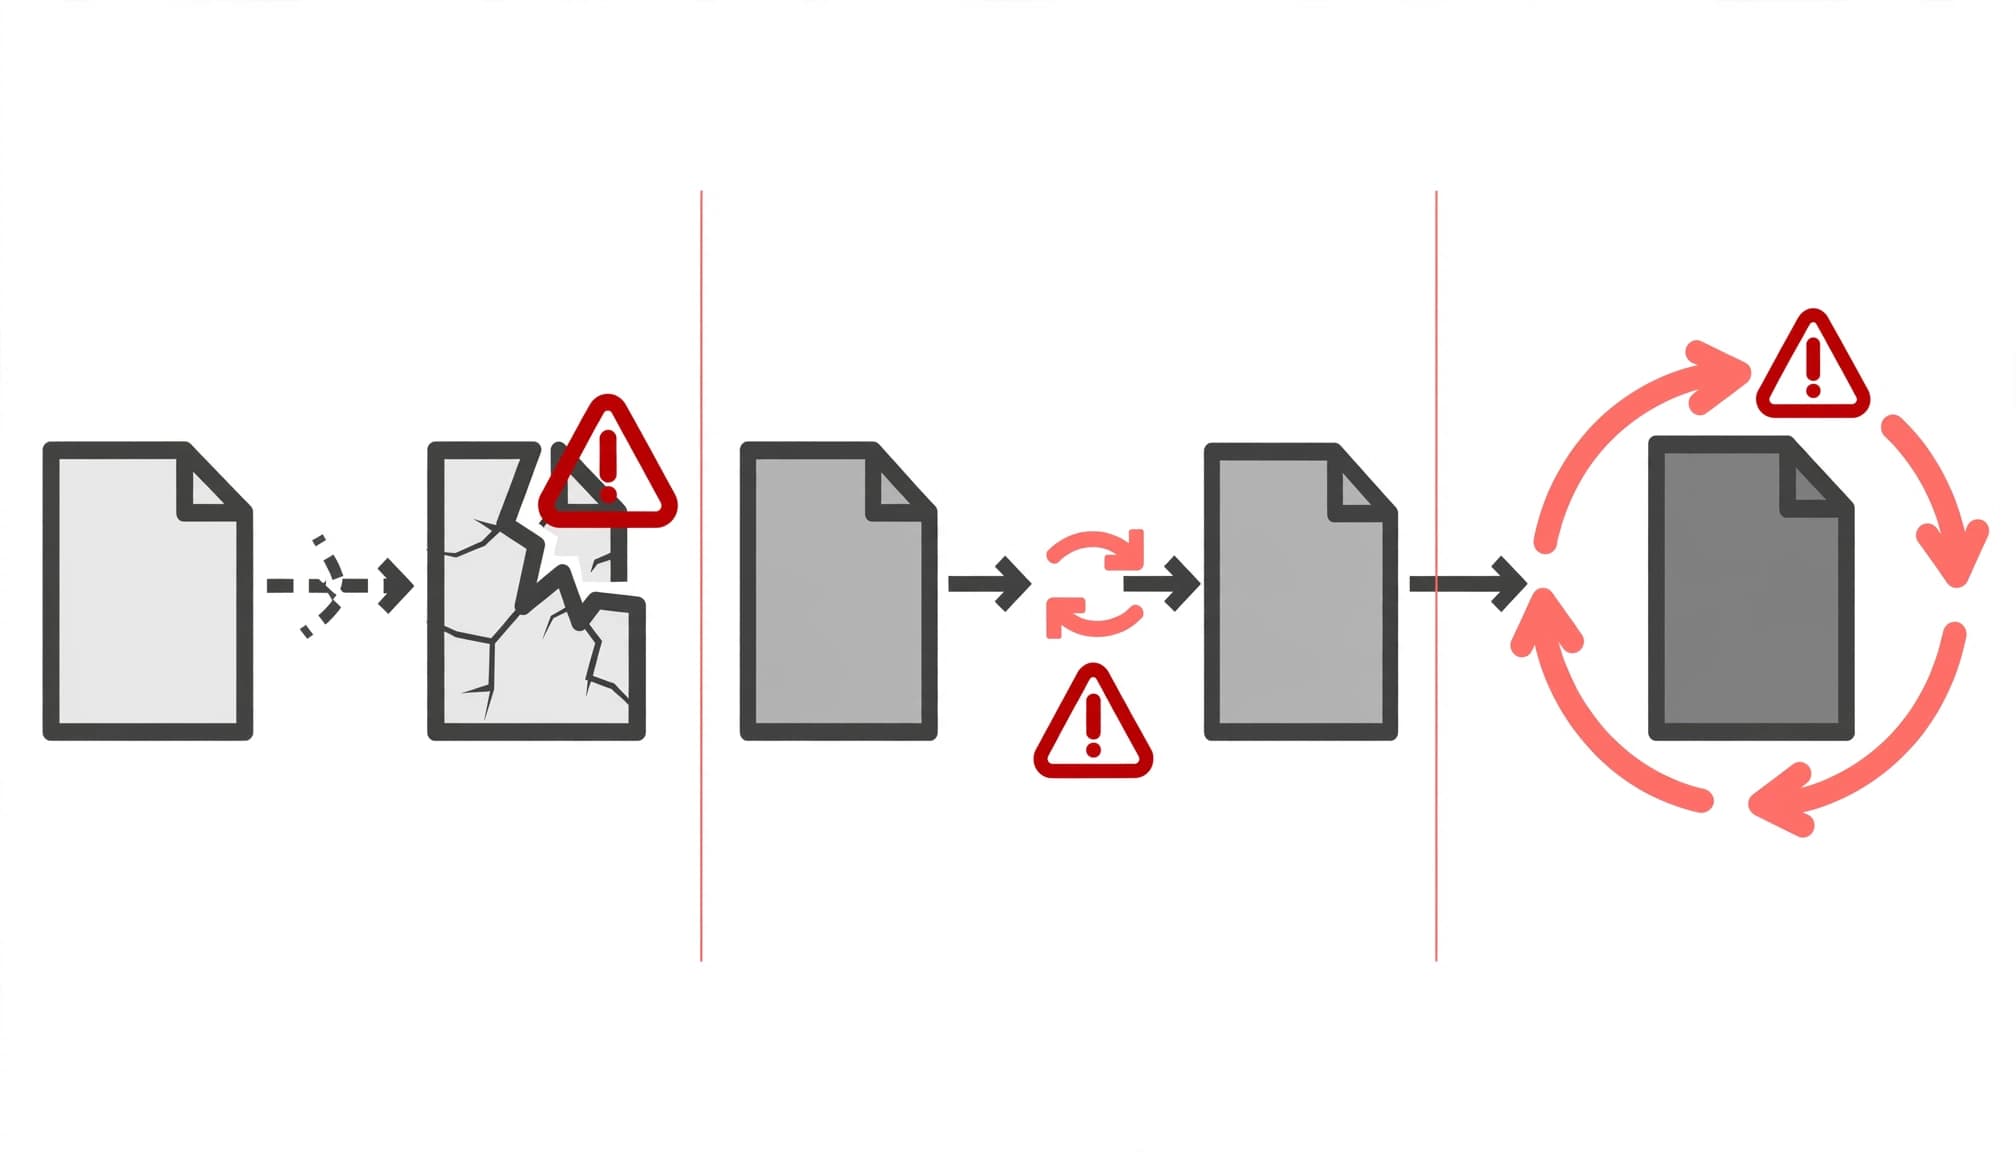
Three panels show a direct route, a multi-hop path, and a circular loop.

Review each finding in order:

  1. Check the expected number of hops and test for a redirect loop by looking for a repeated URL.
  2. Confirm the final page returns a successful HTTP status, usually HTTP 200, and check its status code for a 404 or server error.
  3. Confirm the destination matches the visitor’s original service or location intent.
  4. Flag temporary redirects used for permanent URL changes, and inspect campaign URLs for lost parameters.

A 301 or 308 indicates a permanent redirect; a 302 or 307 indicates a temporary redirect. The HTTP redirect status code reference explains the distinctions. A temporary redirect is valid for a temporary change, so judge the status code against the reason the URL moved.

Triage findings by lead risk, not hop count alone

A green route reaches a lead form while a red route stops at an error symbol.

Redirect chains with several hops deserve attention, but hop count alone won’t tell you what to fix first. Start with URLs that receive paid traffic, attract organic clicks, generate confirmed enquiries, or have valuable backlinks. Compare Search Console performance with GA4, confirmed CRM enquiries, and Semrush’s Site Audit report.

Use this order when assigning repairs:

PriorityRedirect findingFirst action
UrgentBroken path, error, or wrong service page on a live lead pathRestore the correct destination and test the form
HighCampaign URL loses tracking or a busy page has multiple hopsRepair the redirect and retest attribution
RoutineLow-traffic legacy URL reaches the right page after extra hopsShorten the path in the next cleanup

A successful HTTP status, including a 200 status code, doesn’t prove the landing page experience works. The final destination must answer the original request and offer a working way to enquire.

Check any homepage redirects closely. Sending a retired service page there may hide a missing page match and force visitors to restart their search.

Fix chains without losing traffic or link value

Blue and green page tiles connect directly to matching destination tiles on a blueprint.

For a lasting URL move, use a permanent redirect from the original URL to its closest relevant live replacement. Google’s site-move guidance covers URL changes intended to minimize disruption in Search. Keep the original redirect working for visitors and backlinks that still use it. Removing intermediate hops should shorten redirect chains without losing the useful route or link equity to the final destination.

Update internal links and the redirect map

A developer reviews a page structure and printed diagram at a desk.

Update internal links, CTAs, canonical URLs, and sitemap entries to point directly to the final URL. This lets your own site reach the page without extra steps. Next, check important links you control outside the website, including ad destinations, email templates, and business profiles.

For a site migration, document each original URL, replacement, redirect type, and owner in the URL map. Keep a technical SEO record of the changes. If a service has been removed, choose a useful related page only when it answers the same need. The website migration SEO checklist can help your team review URL matches and post-launch checks.

Verify forms, analytics, and campaign tracking

A smartphone and blank checklist sit before simple violet and green analytics shapes.

Open the original URL in a fresh browser session and follow the full path. Submit a consented test enquiry. Confirm that the form succeeds, the notification arrives, and the lead appears in your CRM with the expected source. Test phone and booking CTAs separately if the page uses them.

In GA4 DebugView or Google Tag Manager Preview, confirm that a lead event fires on successful submission, not merely on a button click. Check that it fires once. For paid and email URLs, verify that tracking parameters reach the page; the guide to fixing unassigned GA4 traffic covers redirect-related source loss. Run a post-fix crawl in Semrush to validate the updated paths.

If a scheduler or hosted form changes domains, test that handoff too. A corrected redirect won’t fix attribution that breaks later in the journey.

Choose tools and combine their data efficiently

Three chart-filled reports flow into a prioritized list of colored blocks.

Use Screaming Frog to map URL paths and internal links, and Google Search Console to review search visibility and crawl signals. GA4 and CRM data show whether affected pages generate leads. Include Google Ads destination URLs, the sitemap, and backlink data where available. Semrush can find redirect chains during a technical SEO audit.

Compare Semrush crawl findings with URL paths and search signals to spot gaps. Export Semrush results with the other reports, then join them using the original source URL while retaining the full tagged version for campaign tests. Add columns for the final URL, hop count, issue type, business priority, repair owner, and retest result.

For a small site, a shared spreadsheet is enough. If many locations or campaigns create thousands of URLs, automate repeat checks against the same inventory and use Semrush to review exceptions by page template. If redirect rules, forms, and tracking ownership are split across teams, Get In Touch With Us to coordinate the repair and its conversion tests.

Redirects: Frequently Asked Questions

A business owner checks a phone and laptop at a bright reception counter.

Should every redirect chain have three or fewer hops? Treat three hops as a warning sign, not a guaranteed safe limit or a Google rule. Semrush can help flag longer paths for review. For priority URLs, aim for one direct redirect from the old address whenever possible.

Will changing a temporary redirect to a 301 fix the problem? Only if the move is permanent. Also check where the URL leads, remove extra steps, and confirm the page still supports the intended conversion.

How often should a lead-generation site run this audit? Recheck priority URLs after migrations, campaign launches, domain changes, and redirect-rule edits. A quarterly review can catch older links that reappear in ads, profiles, or email templates.

Can a clean redirect still cause lost leads? Yes. The page might have a broken form, a missing phone CTA, or tracking that loses the campaign source. Test the complete journey before marking the fix done.

Keep redirects short and lead paths intact

A blue route connects a legacy page icon to a landing page and green marker.

The most useful redirect review follows an old link all the way to a confirmed enquiry. It checks the route, the destination, and the source recorded for the lead.

Fix the paths with the greatest lead risk first. Then keep the URL inventory current so future page changes don’t create redirect chains that put another detour between a visitor and your business.

Noindex Audit Checklist for Lead Generation Websites

A laptop showing website pages beside a magnifying glass and checklist.
A lead generation website being reviewed for search visibility

Your strongest service page can look perfect to visitors and still be missing from Google. A misplaced noindex directive can block it from search results, reducing site visibility and organic traffic.

A noindex audit is a practical site audit for search engine optimization. It checks which lead-generation pages should appear in search and whether site rules prevent Google from seeing them. For a lead generation website, start with the pages that bring in calls and form submissions.

Key Takeaways

A glass funnel sorts five web page cards, diverting one marked with a dark tag.
  • List the service, location, and other lead-generating pages you expect Google to index.
  • Check both HTML meta tags and HTTP response headers; either can contain noindex.
  • Compare crawler findings with Google Search Console before changing a site-wide setting.
  • Keep intentional exclusions, such as thank-you pages, while fixing blocked lead pages.
  • Confirm each fix on the live URL and monitor the next crawl.
A website map sits among a target, crawler, graph, and wrench on gridded paper.

Define which lead generation pages need indexing

Four icon-based page cards arranged in two groups on a white board.

Before opening an audit tool, decide what each page is for. A “Not indexed” status is a problem for a valuable service page. For a form confirmation page, it may be exactly right.

As part of your site audit, record each priority URL’s business purpose, intended search query, preferred canonical URL, and conversion action. Add recent organic clicks and qualified leads if you have them. ClickyOwl’s lead-generation SEO audit checklist can help place indexing decisions alongside conversion checks.

Keep valuable service pages indexable

A browser-style page card with a map pin and open doorway icon.

Prioritize valuable pages with ranking potential, such as service, location, industry, comparison, and consultation pages that answer a buyer’s search. A Kolkata service-area page with useful local details and a clear enquiry path may deserve a place in search. If its template carries noindex, every page built from that template could be affected.

Useful, distinct service and location pages should remain eligible for indexing. Near-identical city pages may create duplicate content, so review their quality as well as their directives.

Identify pages that should stay out of search

Three staggered page cards sit behind a translucent screen, with a shield in front.

Thank-you pages, internal search results, and some campaign variants may need to remain accessible without appearing in search. Mark these as intentional exclusions in your inventory so nobody removes their directives during cleanup.

Noindex isn’t access control. If a page contains customer details or confidential files, protect it with authentication rather than relying on a search directive.

Run the noindex audit crawl and collect directive data

A crawler moves across linked sitemap nodes, with crossed-eye symbols on several pages.

Crawl the public site with a tool such as Screaming Frog, Semrush Site Audit, or Sitechecker. Include the XML sitemap and a separate list of important lead pages. A normal crawl can miss a valuable URL with no internal links.

Export each URL’s status code, indexability, robots directive, canonical, and page title. Keep the crawl date and environment with the export, especially around a redesign or migration. Review the site audit findings for any crawl block directive in the robots.txt file. It prevents crawling, but doesn’t itself remove a URL from search results.

Check both HTML and HTTP response headers

A crawler checks a layered web page through two separate inspection paths.

A meta tag in the HTML source code can set a noindex tag with <meta name="robots" content="noindex">. An X-Robots-Tag: noindex can also appear in the HTTP response header. Google’s noindex documentation explains both delivery methods and why Google must crawl the URL to see the rule.

Check the final response after redirects. A directive found on a staging URL doesn’t prove the live destination has the same setting. Likewise, a clean HTML source doesn’t rule out a server-level header. A crawl block directive can also prevent Google from seeing a page-level noindex rule.

Segment URLs by template and business value

Blank page tiles sit in three groups with green and amber status dots.

Group findings into service, location, case study, campaign, and conversion-confirmation templates. Then sort unexpected exclusions by likely lead value. One noindexed quote page deserves faster attention than dozens of intentionally excluded form confirmations.

Look for patterns before fixing URLs individually. If every newly published service page has the same directive, inspect the shared template or publishing settings. If only one page is affected, start with its page-level controls.

Compare the crawl with Google Search Console

Paper reports with page tiles and a chart, separated by a magnifying glass.

Your crawler shows what it can fetch now. Google Search Console shows how Google has classified URLs it knows about. Compare both views rather than treating either as a complete account of the other. A crawl block directive can limit what Google fetches and assesses, but it doesn’t by itself remove a URL from results.

If you haven’t verified the right property or submitted a sitemap, start with Google Search Console setup for lead generation sites. Check that the property covers the live host you’re auditing.

Use the Page Indexing report to spot patterns

A dashboard card shows a coverage chart, excluded page icons, and a magnifying glass over one page.

Open Pages in Search Console and review URLs reported as excluded by noindex. Compare the examples with your inventory: are they thank-you pages, or pages meant to bring in leads? ClickyOwl’s Google Search Console indexing report guide gives more context for the other statuses you may see.

Check the report’s trend around launches and migrations. A jump in excluded service URLs after a template release is more useful evidence than an isolated count. Remember that Search Console reporting can lag behind a live-site change.

Inspect affected URLs one by one

A blue page card sits beside three diagnostic icons in a clean interface.

Use the URL inspection tool for a few high-value pages from each affected template. Review Google’s known indexing status, indexing permission, and canonical selection. Then run a live test to check the current version.

Record the index status beside the crawler finding in your site audit. If the live test no longer detects noindex but the report still shows an exclusion, Google may not have processed the change yet. If both still detect it, keep investigating. Once the live test confirms the URL is eligible, request indexing.

Trace unexpected noindex to its source

A page card sits between three abstract layers in slate, blue, and rust.

Find where the rule is generated before editing it. During your site audit, check whether it comes from a page directive, the robots.txt file, or a response header. A crawl block directive prevents crawling, but doesn’t remove a URL from search results. Otherwise, a page-level change may be overwritten by a template, plugin, or deployment. Save an affected URL and its response details for the person making the fix.

Check CMS and SEO plugin settings

A settings card beside two toggles and a green index symbol.

In your content management system, inspect the site’s search visibility setting and the affected page’s controls. On WordPress, check Yoast SEO or Rank Math, both WordPress plugins. Also review page-level SEO settings, content-type, and taxonomy settings if a whole group of pages is excluded. Change only the setting responsible for the affected URLs.

After saving, clear relevant caches and inspect the live page again. An editor screen showing the right option doesn’t confirm what Googlebot receives.

Review templates, server rules, and deployments

Three connected blocks lead to a page output, with a warning marker on one layer.

For a template-wide problem, review templates, middleware, server configurations, and CDN rules that can add headers. Compare production with staging and check recent releases. Staging often needs exclusion, but that rule must not follow the site into production.

On larger sites, server logs can help confirm whether Googlebot has requested affected URLs since a release. Use Google Search Console Crawl Stats to review broader Googlebot request and server-response patterns.

Fix misconfigured directives safely

Two page cards show a green correction and a separate red restriction symbol.

Remove an accidental noindex only from pages you want indexed, and leave deliberate exclusions in place. After each change, validate fix against the live response. Confirm the URL loads, remains crawlable, and no longer sends noindex in HTML or headers. Record the change in your site audit.

Don’t use a robots.txt file as a fix for an indexing issue. It controls crawling, but a crawl block directive doesn’t remove a URL from search engine results. It can also stop Google from reading a page’s noindex directive. The MDN robots meta documentation notes that the directive takes effect when a crawler revisits the page.

For duplicate content, decide whether both pages need to exist. Use canonical tags to identify a preferred crawlable URL, or redirect an old URL that no longer serves a purpose. Use noindex when a page should remain available but stay out of search, not to force Google to choose another canonical.

If CMS settings, server headers, and migration rules overlap, Get In Touch With Us to identify the source before changing more pages.

Verify the fix and monitor future releases

A branching timeline shifts from warning dots to green checks above a rising traffic line.

Validate fix effectiveness by recrawling the affected template group after deployment. Test at least one service page, location page, and intentionally excluded page where those types exist. This catches fixes that restore indexing to lead pages but accidentally expose thank-you pages. Confirm intended-to-index pages aren’t blocked by a crawl block directive.

Next, run a live URL Inspection test on priority pages and select Request indexing where appropriate. A request asks Google to recrawl, but doesn’t guarantee indexing, a ranking, or an immediate update. Keep corrected, canonical lead pages in your XML sitemap and leave noindexed pages out.

Watch the page indexing report and index status over subsequent crawls. Assess SEO performance by comparing organic traffic, impressions, and clicks in the Google Search Console Performance report. Then check whether enquiries reach your CRM. An indexed page helps only if visits can turn into qualified leads.

Make directive checks part of every template change, migration, and major campaign launch. A periodic site audit can catch older problems, while release checks catch new ones closer to their source.

Frequently asked questions

Four SEO icons show search, server delivery, blocked crawling, and canonical page pairing.

What does “Excluded by noindex tag” mean? Google found a directive telling it not to index the URL. Check whether that matches the page’s purpose before removing anything.

Can a header noindex a page without an HTML tag? Yes. An X-Robots-Tag HTTP response header can carry the directive. The robots meta and X-Robots-Tag guide explains how the two methods differ.

Why might a URL still appear after adding noindex? Google must crawl and revisit the URL to read noindex. Blocking it in a robots.txt file with a crawl block directive doesn’t remove it from search results, and processing takes time.

Should duplicate landing pages use noindex or canonical? If you want Google to understand which similar URL you prefer, use a canonical signal. Reserve noindex for a URL you don’t want indexed at all.

Conclusion

A lead-generation page and search symbol sit before a gently rising traffic chart.

A sound audit protects the pages that bring in enquiries while leaving deliberate exclusions alone. Start with page purpose, trace unexpected directives to their source, and test the live response after each fix.

That turns a hidden indexing problem into a repeatable check your team can run as part of a site audit whenever the website changes.

Robots.txt Audit Checklist for Lead Generation Websites

A glowing site map connects webpage nodes through a secure gateway.
Website crawl paths reach key pages while avoiding low-value sections.

A single misplaced directive can stop search engine crawlers from reaching the page that should bring your next enquiry. For a Kolkata business that depends on service, location, consultation, or quote-request pages, a robots.txt audit protects the routes that support organic lead generation. After validation, your team can request a recrawl for the corrected priority URL, though this doesn’t guarantee immediate indexing.

The robots.txt file has a narrow job, controlling which search engine crawlers may request URLs. It often changes during redesigns, migrations, and CMS updates, so include protocol, host, and subdomain scanning in a broader technical SEO audit, since each host may have its own file. Review rendering, indexing, and conversion checks too. Reducing requests to low-value paths can protect crawl budget and inform an AI readiness score, but it doesn’t guarantee rankings.

Understand Crawling, Indexing, and Lead Value

A crawler follows webpage paths beside a stacked search index illustration.

A robots.txt file tells compliant crawlers which URLs they may request. Google explains in its robots.txt introduction that the file mainly manages crawling, including limiting unnecessary requests to a site.

That makes it a useful part of technical SEO. However, crawl access doesn’t decide search indexing, rankings, or qualified leads. Begin every review with a list of pages that matter commercially.

Crawling is not the same as indexing

A central website gateway directs allowed and restricted routes to three subdomains.

Crawling means Googlebot fetches a URL and its needed resources. Indexing means Google decides it can store and potentially show that page in search results. Crawl access is a prerequisite for Google to evaluate a page for search indexing, but it isn’t an indexing decision itself.

A URL blocked by robots.txt can still appear in Google and search engine results if another site or internal page exposed it.

Use a noindex meta robots tag or HTTP header when a public page should leave the index. Don’t block that same URL in robots.txt, because Google then may not fetch the directive. Use a 301 redirect for a replacement page, or a 410 response when content has permanently gone. Once the rule, noindex state, or redirect is validated, you can request a recrawl for the affected URL.

Canonical tags handle a different problem. They tell search engines which version of similar pages is preferred. A canonical selects a preferred duplicate, but it isn’t a dependable removal method.

Identify the pages that deserve crawler access

Abstract robots.txt checklist board with four checkpoints, a magnifying glass, and browser window.

Create a priority inventory before reading directives. Include service pages, industry pages, location pages, pricing pages, case studies, comparison pages, and contact routes. Also record each page’s intended conversion, canonical URL, organic clicks, and verified lead outcome.

An AI readiness score can separately assess crawler access, rendering, and content availability. Treat it as a diagnostic, not a Google ranking metric.

Thank-you pages, login areas, internal search results, duplicate filter pages, staging routes, and test pages usually need different treatment. A lean index can outperform a large one when it contains pages that match real buying intent.

For wider checks across crawlability, conversion paths, and analytics, use this lead generation SEO audit checklist.

Run the Core Robots.txt Audit Checklist

A document with branching colored paths and check marks for validating crawler rules.

Start with the live file, not a copied version in a developer folder. It must be served from the domain root of the exact host, such as https://example.com/robots.txt. Review HTTP status codes, redirects, and 404 responses.

Each host needs its own review. A file on the www version does not automatically control a non-www host, subdomain, or separate shop. Include subdomain scanning for the public website, blog, help centre, app, and campaign hosts if they can attract search traffic.

Validate user-agent groups and directives

A sitemap network, server lights, and one crawler route in a blue and teal infographic.

Check every user-agent group, disallow directive, and allow directive. Confirm how each allow directive interacts with a broader disallow rule. Review each user-agent group independently, since copied rules can create unexpected access.

Watch for rules left over from a staging launch, an old CMS, or a security plugin. Perform syntax validation before publishing changes, then use a reputable robots.txt checker as a secondary validation method. Source review, live testing, and crawler documentation remain necessary.

Invalid syntax, misplaced wildcards, and malformed groups can cause parsing issues and unexpected crawler behaviour. Confirm the file follows the Robots Exclusion Protocol in RFC 9309. Keep comments simple, and avoid adding rules until you know which crawler requests you want to reduce.

A blocked lead page may look perfect to visitors while Googlebot cannot fetch it at all.

Robots.txt is not a security tool or access control. Never reveal confidential folders, credentials, customer documents, or private assets through a public file. Protect sensitive material with authentication and proper server access controls to maintain a strong security posture and avoid sensitive path disclosures.

If a blocking rule affects a high-value URL, correct and test it first. Then request a recrawl for that URL, but don’t treat the request as a guarantee.

Check sitemap declarations and response codes

Abstract service and location pages connect through an orange conversion path.

Verify all sitemap declarations in the file, then open the XML sitemap and every child sitemap. Each should return a 200 status and use the current HTTPS domain. Review HTTP status codes, redirects, and 404 responses during this check. A migration can leave an old sitemap URL that now redirects or returns a 404.

Keep only canonical, indexable URLs in the sitemap. Remove redirects, broken pages, parameter variations, noindex thank-you pages, and staging URLs. Sitemap and canonical signals should agree with the pages you want Google to discover.

Verified access, valid responses, and renderable resources can contribute to an AI readiness score. They don’t replace human review of crawl behaviour and business priorities.

Protect Pages That Move Visitors Toward Contact

Browser cards show a public conversion path with a private admin area outside it.

A strong service page cannot produce enquiries if search engines cannot crawl or render it, or if its form fails after landing. Test priority routes as a connected path: search result, landing page, CTA, form submission, and confirmation screen.

Keep the public service, contact, consultation, and supporting proof pages crawlable. Usually, the confirmation page can remain noindexed because it has no independent search value.

Do not block CSS, JavaScript, or form resources

CSS and JavaScript streams feed a webpage while one crawler inspects it.

Modern sites often load headings, testimonials, prices, form fields, and internal links through JavaScript. A robots.txt file should not block resources Google needs to render visible content or understand internal links.

Use a browser extension or browser network panel to compare loaded CSS, JavaScript, images, API content, and form resources with what URL Inspection reports. Confirm those findings with a crawl using Screaming Frog or Sitebulb. Incomplete rendering can affect how Google evaluates content for search indexing and lead conversion.

Successful rendering of important content is one input to an AI readiness score, but it doesn’t guarantee AI citations or visibility. Investigate 403 responses, 5xx errors, redirect chains, timeouts, consent walls, and accidental noindex rules.

After making a previously blocked script, stylesheet, API resource, or priority page accessible, test it again and request a recrawl for the affected URL where appropriate.

A JavaScript SEO audit for lead generation sites can help when key content or conversion elements depend on client-side rendering.

Give important pages clear internal routes

Three crawler symbols approach a central gate along separate colored paths.

Robots.txt cannot repair weak internal linking. Link to money pages from relevant service hubs, location hubs, articles, and case studies with descriptive anchors. A valuable page buried several clicks deep or left orphaned may receive little crawler attention.

Review crawl depth as a tie-breaker when several issues compete for attention. Fix a blocked page that earns enquiries before spending time on harmless tracking URLs.

Set Separate Rules for Search and AI Crawlers

A policy board separates two crawler lanes leading toward a website icon.

AI crawler decisions now belong in the same audit, but they shouldn’t be mixed with Googlebot rules. Different AI crawlers may have separate identities and purposes. Your policy should reflect business goals, content rights, server capacity, and how each crawler uses retrieved material.

Keep a dated record of every bot-related change. Test Google-facing access rules first, then an owner can request a recrawl for affected Google URLs. This doesn’t force an AI platform to return or guarantee AI search visibility.

Distinguish training from search access

A balanced gauge surrounded by crawl paths, webpage cards, and policy symbols.

AI platforms may use separate user-agent tokens for model training and search or retrieval. For example, OpenAI distinguishes GPTBot from OAI-SearchBot. Anthropic and Perplexity also use more than one crawler identity.

Blocking GPTBot can limit training data collection without blocking search retrieval. Allowing one token doesn’t grant access to every bot from that company. Review each published token, then decide whether it can access relevant public content.

Treat an AI readiness score as a working rubric

A browser test connects to a server response and ongoing monitoring timeline.

There is no universal AI readiness score that guarantees citations or visibility. A practical internal score can still expose gaps when it measures crawler access, policy clarity, 200-status priority pages, rendering access, useful content, and consistent business information.

Use an AI readiness score as an internal rubric, not a universal ranking or citation metric. Score platforms separately rather than blending every crawler into one number. A clear policy is more useful than a high-looking score that hides blocked service pages or unreliable server responses.

Test, Monitor, and Record Changes

Abstract monitor showing robots file checks, host nodes, fetch status, and warning icons.

Test after every robots.txt edit, CMS update, template release, security-rule change, or migration. Repeat syntax validation, then check priority URLs instead of assuming the correction worked. After validating a correction to a priority URL, request a recrawl through URL Inspection. Google ultimately re-fetches robots.txt changes on its own schedule.

Use Search Console and crawl checks together

Four server nodes connect to a central timeline showing a tracked file change.

Google Search Console’s robots.txt report shows files Google found for the top 20 hosts, their last crawl dates, and reported warnings. Check it alongside URL Inspection and the Page Indexing report.

Review the live XML sitemap for 200 responses, canonical HTTPS URLs, and no redirects or staging URLs. After manual review and Search Console checks, use a robots.txt checker, but don’t treat automated output as a substitute for testing live URLs.

For site-level patterns, review server responses and Googlebot requests with Google Search Console Crawl Stats. Rising crawl errors can affect priority URLs and require prompt investigation. Compare recurring parsing issues with deployment history and server logs rather than dismissing them as harmless warnings. Repeated access, response, or rendering failures can also lower an internally tracked AI readiness score, though it doesn’t predict rankings or citations.

Maintain a host-by-host change log

Four connected icons show key robots.txt audit priorities around a website symbol.

Record the date, affected host, directive changed, owner, reason, and validation result. Use subdomain scanning to check the main site, blog, app, and campaign hosts separately.

Run a full review quarterly. Recheck sooner after redesigns, tracking updates, hosting changes, or a sudden fall in impressions on important service pages.

Key Takeaways

Four question cards surround a central robots.txt file icon with colorful technical symbols.
  • Keep high-value service, location, and contact pages accessible to Googlebot. After correcting blocked URLs, validate them and request a recrawl where appropriate.
  • Use noindex, redirects, or 410 responses for removal goals, not robots.txt alone.
  • Check each protocol, subdomain, sitemap, and priority URL separately.
  • Leave required CSS, JavaScript, and form resources available for rendering.
  • Record an AI readiness score as an internal diagnostic. Evaluate platforms separately, and never treat it as proof of search or AI visibility.

FAQ

Website architecture with an open green path, conversion symbol, and audit shield.

What is the primary purpose of robots.txt? It guides compliant crawlers away from areas you don’t want them to request, often to reduce unnecessary crawling. It doesn’t secure private content or guarantee removal from search results.

Where should the robots.txt file sit? Put it at the domain root of the exact host, such as https://example.com/robots.txt. Review separate files for subdomains and alternate hosts. Subdomain scanning is also needed when blogs, apps, campaign hosts, or help centres can attract search traffic.

How often should a lead-generation website audit robots.txt? Check it quarterly and after any website launch, migration, plugin change, template update, tracking deployment, or security configuration change.

Can I block a page that already appears in Google? Blocking it may stop Google from seeing a future noindex directive. Keep crawling available so Google can read the meta robots tag, then use noindex, a relevant redirect, or a 410 response based on the page’s purpose. After correcting the issue, you can request a recrawl for the affected URL, but this doesn’t guarantee immediate removal or indexing.

Keep Crawl Access Tied to Business Goals

A good robots.txt file does not try to control every URL. It keeps unnecessary paths out of the crawl queue while leaving your most useful pages easy to fetch, render, and understand.

Review robots.txt audit findings alongside indexing, page quality, form tracking, and CRM outcomes. Crawl access, rendering, and response reliability may contribute to an AI readiness score, but business goals and real lead outcomes remain the priority. If an important page is blocked or broken, Get In Touch With Us to diagnose the issue before it costs more qualified enquiries. After fixing and validating the page, request a recrawl for the URL, then monitor impressions and leads. Clear crawler policies can support AI search visibility, but they can’t guarantee citations, rankings, or enquiries.

A/B Testing Landing Pages Without Losing Lead Data

Analyst viewing two landing page designs beside analytics and CRM icons in a bright office.
Two landing page variants connect through a funnel to one lead icon.

A/B testing landing pages can raise form submissions, but a flawed setup can also create duplicate leads, missing campaign sources, and misleading winners.

For a small business in Kolkata, reliable lead generation matters because every qualified enquiry counts. If the test changes conversion tracking or breaks the CRM handoff, higher dashboard numbers may hide weaker sales results.

A sound experiment improves the page while keeping the measurement path stable.

A/B Testing Landing Pages: Protect the Data Before Chasing a Lift

Matching records follow two colored paths into a transparent database.

A/B testing compares a control version against one changed version. Randomly divide eligible unique visitors between the page variations, then measure the same primary outcome for both groups.

The goal isn’t a prettier page or higher click through rates. Conversion rate optimization focuses on conversion rate and lead generation, not clicks alone. It should produce more real leads your team can contact, qualify, and connect to revenue.

Count qualified leads, not every form action

Abstract tokens follow a bright path toward a lead form as faint routes fade behind it.

A page variation may generate more submissions but attract spam, incomplete enquiries, or poor-fit prospects. Track the initial generate_lead event, then compare booked calls, sales-qualified leads, and closed deals in the CRM.

This matters for marketing campaigns and SEO alike. A service page that produces fewer but better enquiries can outperform a high-volume page.

Change one decision at a time

Three colorful experiment cards arranged in sequence along a horizontal timeline.

Start with test hypotheses grounded in visible issues. For example, a shorter form may increase confirmed submissions because visitors abandon the phone-number field.

Test the form length, not a new headline, visual, offer, and button at once. One controlled change makes the result easier to interpret. Test headlines, call to action wording, social proof, form fields, and layout order in separate rounds.

Build Measurement Before You Create Variants

Three connected data layers support two experimental panels in a clean navy and teal studio.

Tracking should exist before traffic reaches either page variation. Write down the conversion definition, event names, attribution fields, CRM fields, sample size, and integration owner for every connection.

A useful baseline is a GA4 lead tracking checklist that separates meaningful lead events from soft engagement signals, including the confirmed lead-generation outcome you’re measuring.

Keep IDs and event schemas consistent

Connected teal and coral nodes show a highlighted form submission event.

Pass an experiment_id, variant_id, landing_page, and form_id with the same event schema on both variants. Don’t rename events on Version B or create a separate GA4 conversion for it.

Use stable anonymous IDs to assign unique visitors, then attach the CRM’s lead ID after successful submission. Keep personal details out of analytics events. Clear GA4 event naming conventions make later analysis far less error-prone.

Validate a confirmed success event

A landing form connects through analytics to a CRM record with three green checks.

A thank-you page can support follow-up messaging, but it shouldn’t be the only proof of a conversion. Reloads, direct visits, and bot traffic can inflate page-based counts.

Fire the primary conversion only after the form passes validation and the lead record or booking is confirmed.

Use GA4 DebugView, Tag Manager Preview, and a CRM test record as testing tools before launch. Before releasing traffic, validate consent status, stable IDs, event schemas, CRM lead IDs, deduplication logic, and fields needed for historical reporting. Event tracking versus thank-you pages explains why confirmed actions give cleaner lead attribution.

CheckExpected result
Page loadOne page view per load
Form submitEvent fires only after success
Variant fieldControl or variation is present
CRM handoffOne lead record receives the same ID
AttributionUTMs and click IDs persist

Choose the Right Experiment Delivery Method

Browser and server experiments connect to the same landing page and analytics destination.

A/B tests and split testing both compare alternatives. Teams often use separate page URLs for split testing, while an A/B test may change page variations on the same URL. Multivariate testing evaluates combinations of several changes, so it needs more traffic and disciplined analysis.

Keep traffic distribution consistent among eligible unique visitors. Persist assignment across the session and relevant return visits, so each group receives its intended landing page variants.

Client-side tests are quick, but watch performance

A page panel, request flow, and performance gauge in a bright abstract web studio.

Client-side testing tools load the original page, then modify the browser DOM after delivery. This can be practical for copy, buttons, and small layout changes.

However, delayed scripts can cause a brief visual flicker or slow page speed, affecting the user experience. Test on mobile networks and check that both variants load the same form, consent controls, and tracking tags.

Server-side tests give tighter control

A glowing request branches through servers toward one of two identical page layouts.

Server-side testing assigns a variation before the page renders. It suits major page changes, logged-in experiences, pricing logic, or cases where performance matters.

The setup usually needs developer support. In return, it can record the assigned variant in backend logs and send a more consistent page response. Google documents how a third-party experiment integration can connect with GA4.

Plan Traffic, Minimum Detectable Effect, and Test Duration

A circular weekly path surrounds two equal experiment containers with visitor tokens.

Traffic alone doesn’t decide whether a test is reliable. Sample size depends on baseline conversion rate, the lift worth detecting, traffic distribution, and the uncertainty you can accept.

Set the test duration, sample size, and decision rule before launch. Otherwise, it’s tempting to stop when test results briefly look positive.

Define the smallest useful improvement

Two conversion bars show a small highlighted gap beside visitor tokens.

Your minimum detectable effect is the smallest conversion-rate change that would justify the effort or risk. A small uplift may not cover additional ad spend or sales follow-up, while a large target may demand more traffic than the campaign can supply.

Record the baseline, planned sample, decision rule, start date, and expected sales lag. A disciplined A/B test tracking approach keeps these details visible. Refer back to the minimum detectable effect threshold when evaluating the outcome.

Low-traffic sites should test less often

Sparse visitor tokens collect in two transparent containers along separate paths.

There is no universal monthly visitor threshold. Traffic estimates should reflect eligible unique visitors, not raw page loads. With limited traffic, focus on high-intent campaigns, run one test longer, and avoid multivariate testing.

Include normal weekday and weekend behaviour where relevant. A seven-day run can reduce calendar bias, but it doesn’t guarantee statistical significance. Wait for the planned sample and inspect lead quality before choosing a winner.

Preserve Attribution Through the CRM Handoff

One lead path connects a campaign source, landing page, form, and CRM with attached colored markers.

Visitors rarely convert on their first page during lead generation. They may arrive through Google Ads or other marketing campaigns, browse service pages, return through branded search, then submit a form several days later.

Capture attribution on entry and preserve it across visits and channels until the CRM receives the lead.

Store source data and prevent duplicates

One lead card moves from a web form through checks into a sales pipeline.

With appropriate consent, store UTM parameters and click identifiers such as GCLID, WBRAID, and GBRAID in first-party storage. Then repopulate approved hidden inputs if the visitor moves between pages.

Pass first-touch source, latest source, landing page, referrer, experiment ID, variant ID, and a conversion timestamp into the CRM. Use a unique submission or lead ID to deduplicate repeat submits, confirmation-page reloads, and double-fired tags.

Reconcile web reports with sales outcomes

Analytics and CRM pipelines meet as matching lead records align at a central table.

GA4 is useful for landing-page performance and channel patterns. Your CRM should remain the source for lead status, opportunities, revenue, and closed sales.

Review both reports on a fixed schedule. Compare web test results with CRM lead status, opportunity, revenue, and closed-sale outcomes. Compare lead IDs, variant assignment, source fields, and date ranges. The process in this GA4 CRM reconciliation guide helps expose missing handoffs and inflated web conversions.
Browser blockers, consent choices, private browsing, embedded schedulers, and cross-domain journeys can all create gaps. Server-side tracking may improve first-party control, but it can’t replace consent or reconstruct every journey.

Read Results Carefully and Pick Tools That Fit

Wall chart showing two conversion curves, uncertainty bands, and a highlighted decision area.

Test results can be inconclusive because statistical significance isn’t automatic. The proposed change may be too small, the page may need more traffic, or the test may have run during an unusual promotion.

Review the planned sample size, unique visitors, traffic split, test duration, technical QA, conversion rate, and downstream lead quality. Keep denominator and segment definitions consistent. Segment carefully by device and channel, because a mobile form issue can disappear inside an overall average user experience. GA4 funnel explorations can reveal where each variant loses visitors.

A landing page builder can help non-technical teams create page variations and landing page variants. Before choosing testing tools, confirm current pricing, experiment allocation, GA4 integration, CRM support, page-speed impact, access controls, and support for conversion rate optimization. Keep an experiment log even when the tool offers automated reporting.

If form submissions rise but qualified leads fall, don’t treat the higher count as a winning variation. Retain the control because lead generation quality matters. If tracking disagrees across platforms, pause further changes and Get In Touch With Us before scaling spend.

Key Takeaways

Four colorful modules surround a central verified symbol in a polished analytics studio.
  • Treat a confirmed lead action, not a page view or button click, as the primary conversion.
  • Keep IDs, event names, attribution fields, and CRM mappings identical across control and variation.
  • Decide sample size, duration, and the minimum useful lift before traffic enters the experiment.
  • Judge a winning variation by qualified pipeline, not form fills alone.

Frequently Asked Questions

Abstract question markers beside a landing page, sample container, and conversion path.

How much traffic does a landing-page A/B test need? It depends on your baseline conversion rate, required sample size, and the change you need to detect. Low-traffic businesses should assess available unique visitors, run fewer tests, focus on larger page changes, and use CRM outcomes. A traffic estimate alone doesn’t guarantee a reliable result.

How long should a test run? Run until the planned sample arrives and the test covers ordinary business patterns. Don’t call a winner early because a dashboard spikes for a day.

What should you test first? Start with the largest source of friction: an unclear offer, weak messaging, poor message match, or an overly demanding form. Analytics and customer feedback should guide the hypothesis.

Can conversion data be trusted when privacy limits tracking? It can still guide decisions when teams respect consent, validate confirmed events, preserve first-party identifiers where permitted, and reconcile web data with CRM records.

Clean Data Makes A/B Tests Worth Running

Two experiment panels merge into one clear path toward a business outcome marker.

A landing-page experiment is only as useful as the conversion record behind it. Stable tracking, preserved attribution, and CRM reconciliation make the test results trustworthy.

The strongest tests produce a winning variation that improves lead quality, preserves attribution, and leaves a clear audit trail from the first click through the sales outcome.

A/B Testing Landing Pages Without Losing Lead Data

Analyst viewing two landing page designs beside analytics and CRM icons in a bright office.
Two landing page variants connect through a funnel to one lead icon.

A/B testing landing pages can raise form submissions, but a flawed setup can also create duplicate leads, missing campaign sources, and misleading winners.

For a small business in Kolkata, reliable lead generation matters because every qualified enquiry counts. If the test changes conversion tracking or breaks the CRM handoff, higher dashboard numbers may hide weaker sales results.

A sound experiment improves the page while keeping the measurement path stable.

A/B Testing Landing Pages: Protect the Data Before Chasing a Lift

Matching records follow two colored paths into a transparent database.

A/B testing compares a control version against one changed version. Randomly divide eligible unique visitors between the page variations, then measure the same primary outcome for both groups.

The goal isn’t a prettier page or higher click through rates. Conversion rate optimization focuses on conversion rate and lead generation, not clicks alone. It should produce more real leads your team can contact, qualify, and connect to revenue.

Count qualified leads, not every form action

Abstract tokens follow a bright path toward a lead form as faint routes fade behind it.

A page variation may generate more submissions but attract spam, incomplete enquiries, or poor-fit prospects. Track the initial generate_lead event, then compare booked calls, sales-qualified leads, and closed deals in the CRM.

This matters for marketing campaigns and SEO alike. A service page that produces fewer but better enquiries can outperform a high-volume page.

Change one decision at a time

Three colorful experiment cards arranged in sequence along a horizontal timeline.

Start with test hypotheses grounded in visible issues. For example, a shorter form may increase confirmed submissions because visitors abandon the phone-number field.

Test the form length, not a new headline, visual, offer, and button at once. One controlled change makes the result easier to interpret. Test headlines, call to action wording, social proof, form fields, and layout order in separate rounds.

Build Measurement Before You Create Variants

Three connected data layers support two experimental panels in a clean navy and teal studio.

Tracking should exist before traffic reaches either page variation. Write down the conversion definition, event names, attribution fields, CRM fields, sample size, and integration owner for every connection.

A useful baseline is a GA4 lead tracking checklist that separates meaningful lead events from soft engagement signals, including the confirmed lead-generation outcome you’re measuring.

Keep IDs and event schemas consistent

Connected teal and coral nodes show a highlighted form submission event.

Pass an experiment_id, variant_id, landing_page, and form_id with the same event schema on both variants. Don’t rename events on Version B or create a separate GA4 conversion for it.

Use stable anonymous IDs to assign unique visitors, then attach the CRM’s lead ID after successful submission. Keep personal details out of analytics events. Clear GA4 event naming conventions make later analysis far less error-prone.

Validate a confirmed success event

A landing form connects through analytics to a CRM record with three green checks.

A thank-you page can support follow-up messaging, but it shouldn’t be the only proof of a conversion. Reloads, direct visits, and bot traffic can inflate page-based counts.

Fire the primary conversion only after the form passes validation and the lead record or booking is confirmed.

Use GA4 DebugView, Tag Manager Preview, and a CRM test record as testing tools before launch. Before releasing traffic, validate consent status, stable IDs, event schemas, CRM lead IDs, deduplication logic, and fields needed for historical reporting. Event tracking versus thank-you pages explains why confirmed actions give cleaner lead attribution.

CheckExpected result
Page loadOne page view per load
Form submitEvent fires only after success
Variant fieldControl or variation is present
CRM handoffOne lead record receives the same ID
AttributionUTMs and click IDs persist

Choose the Right Experiment Delivery Method

Browser and server experiments connect to the same landing page and analytics destination.

A/B tests and split testing both compare alternatives. Teams often use separate page URLs for split testing, while an A/B test may change page variations on the same URL. Multivariate testing evaluates combinations of several changes, so it needs more traffic and disciplined analysis.

Keep traffic distribution consistent among eligible unique visitors. Persist assignment across the session and relevant return visits, so each group receives its intended landing page variants.

Client-side tests are quick, but watch performance

A page panel, request flow, and performance gauge in a bright abstract web studio.

Client-side testing tools load the original page, then modify the browser DOM after delivery. This can be practical for copy, buttons, and small layout changes.

However, delayed scripts can cause a brief visual flicker or slow page speed, affecting the user experience. Test on mobile networks and check that both variants load the same form, consent controls, and tracking tags.

Server-side tests give tighter control

A glowing request branches through servers toward one of two identical page layouts.

Server-side testing assigns a variation before the page renders. It suits major page changes, logged-in experiences, pricing logic, or cases where performance matters.

The setup usually needs developer support. In return, it can record the assigned variant in backend logs and send a more consistent page response. Google documents how a third-party experiment integration can connect with GA4.

Plan Traffic, Minimum Detectable Effect, and Test Duration

A circular weekly path surrounds two equal experiment containers with visitor tokens.

Traffic alone doesn’t decide whether a test is reliable. Sample size depends on baseline conversion rate, the lift worth detecting, traffic distribution, and the uncertainty you can accept.

Set the test duration, sample size, and decision rule before launch. Otherwise, it’s tempting to stop when test results briefly look positive.

Define the smallest useful improvement

Two conversion bars show a small highlighted gap beside visitor tokens.

Your minimum detectable effect is the smallest conversion-rate change that would justify the effort or risk. A small uplift may not cover additional ad spend or sales follow-up, while a large target may demand more traffic than the campaign can supply.

Record the baseline, planned sample, decision rule, start date, and expected sales lag. A disciplined A/B test tracking approach keeps these details visible. Refer back to the minimum detectable effect threshold when evaluating the outcome.

Low-traffic sites should test less often

Sparse visitor tokens collect in two transparent containers along separate paths.

There is no universal monthly visitor threshold. Traffic estimates should reflect eligible unique visitors, not raw page loads. With limited traffic, focus on high-intent campaigns, run one test longer, and avoid multivariate testing.

Include normal weekday and weekend behaviour where relevant. A seven-day run can reduce calendar bias, but it doesn’t guarantee statistical significance. Wait for the planned sample and inspect lead quality before choosing a winner.

Preserve Attribution Through the CRM Handoff

One lead path connects a campaign source, landing page, form, and CRM with attached colored markers.

Visitors rarely convert on their first page during lead generation. They may arrive through Google Ads or other marketing campaigns, browse service pages, return through branded search, then submit a form several days later.

Capture attribution on entry and preserve it across visits and channels until the CRM receives the lead.

Store source data and prevent duplicates

One lead card moves from a web form through checks into a sales pipeline.

With appropriate consent, store UTM parameters and click identifiers such as GCLID, WBRAID, and GBRAID in first-party storage. Then repopulate approved hidden inputs if the visitor moves between pages.

Pass first-touch source, latest source, landing page, referrer, experiment ID, variant ID, and a conversion timestamp into the CRM. Use a unique submission or lead ID to deduplicate repeat submits, confirmation-page reloads, and double-fired tags.

Reconcile web reports with sales outcomes

Analytics and CRM pipelines meet as matching lead records align at a central table.

GA4 is useful for landing-page performance and channel patterns. Your CRM should remain the source for lead status, opportunities, revenue, and closed sales.

Review both reports on a fixed schedule. Compare web test results with CRM lead status, opportunity, revenue, and closed-sale outcomes. Compare lead IDs, variant assignment, source fields, and date ranges. The process in this GA4 CRM reconciliation guide helps expose missing handoffs and inflated web conversions.
Browser blockers, consent choices, private browsing, embedded schedulers, and cross-domain journeys can all create gaps. Server-side tracking may improve first-party control, but it can’t replace consent or reconstruct every journey.

Read Results Carefully and Pick Tools That Fit

Wall chart showing two conversion curves, uncertainty bands, and a highlighted decision area.

Test results can be inconclusive because statistical significance isn’t automatic. The proposed change may be too small, the page may need more traffic, or the test may have run during an unusual promotion.

Review the planned sample size, unique visitors, traffic split, test duration, technical QA, conversion rate, and downstream lead quality. Keep denominator and segment definitions consistent. Segment carefully by device and channel, because a mobile form issue can disappear inside an overall average user experience. GA4 funnel explorations can reveal where each variant loses visitors.

A landing page builder can help non-technical teams create page variations and landing page variants. Before choosing testing tools, confirm current pricing, experiment allocation, GA4 integration, CRM support, page-speed impact, access controls, and support for conversion rate optimization. Keep an experiment log even when the tool offers automated reporting.

If form submissions rise but qualified leads fall, don’t treat the higher count as a winning variation. Retain the control because lead generation quality matters. If tracking disagrees across platforms, pause further changes and Get In Touch With Us before scaling spend.

Key Takeaways

Four colorful modules surround a central verified symbol in a polished analytics studio.
  • Treat a confirmed lead action, not a page view or button click, as the primary conversion.
  • Keep IDs, event names, attribution fields, and CRM mappings identical across control and variation.
  • Decide sample size, duration, and the minimum useful lift before traffic enters the experiment.
  • Judge a winning variation by qualified pipeline, not form fills alone.

Frequently Asked Questions

Abstract question markers beside a landing page, sample container, and conversion path.

How much traffic does a landing-page A/B test need? It depends on your baseline conversion rate, required sample size, and the change you need to detect. Low-traffic businesses should assess available unique visitors, run fewer tests, focus on larger page changes, and use CRM outcomes. A traffic estimate alone doesn’t guarantee a reliable result.
How long should a test run? Run until the planned sample arrives and the test covers ordinary business patterns. Don’t call a winner early because a dashboard spikes for a day.

What should you test first? Start with the largest source of friction: an unclear offer, weak messaging, poor message match, or an overly demanding form. Analytics and customer feedback should guide the hypothesis.

Can conversion data be trusted when privacy limits tracking? It can still guide decisions when teams respect consent, validate confirmed events, preserve first-party identifiers where permitted, and reconcile web data with CRM records.

Clean Data Makes A/B Tests Worth Running

Two experiment panels merge into one clear path toward a business outcome marker.

A landing-page experiment is only as useful as the conversion record behind it. Stable tracking, preserved attribution, and CRM reconciliation make the test results trustworthy.

The strongest tests produce a winning variation that improves lead quality, preserves attribution, and leaves a clear audit trail from the first click through the sales outcome.

XML Sitemap Audit Checklist for Lead Generation Websites

Laptop showing a connected website map beside a magnifying glass.

A lead-generation website can have excellent service pages and still lose enquiries when Google can’t reliably find or index them. A focused xml sitemap audit shows whether your sitemap supports the pages that bring calls, form submissions, demo requests, and consultation bookings.

For a business site, the goal isn’t to get every URL into Google. Help valuable service and location pages reach the search engine index without wasting crawl budget. Treat the review as a focused crawl analysis of URLs with real commercial value.

What an XML Sitemap Audit Should Prove

Sitemap document and funnel with validation markers over connected website nodes.

An XML sitemap is a discovery file, not an indexation guarantee. A sitemap index file helps search engines find submitted URLs, but it can’t guarantee inclusion in search results. Google can still exclude a page because of weak content, duplicate signals, a conflicting canonical url, or a noindex directive.

A useful audit confirms that priority service, industry, comparison, and location pages are easy for Googlebot to find. It also checks that files follow the xml sitemaps protocol and exclude URLs with no organic search value, such as thank-you pages, login pages, campaign parameters, and staging routes.

A clean sitemap makes Search Console reporting more useful because the sitemap filter contains pages you deliberately want to appear in search.

For lead generation, this distinction matters. A site with fewer indexed URLs can outperform a larger one when its indexed pages match real buying searches. Pair sitemap checks with technical seo and crawl analysis using a broader lead-generation SEO audit checklist to review conversion paths, page intent, and measurement.

Find Every Sitemap Before Testing It

A crawler follows branching routes from a server toward a sitemap file.

Inspect robots.txt and familiar sitemap locations

Start sitemap discovery with an xml sitemap audit by locating every declared and generated file.

Pass: The site’s robots.txt file declares the active sitemap URL, and the file loads publicly.

Fail: The declaration returns a 404 error, points to an old domain, or lists a sitemap that no longer exists.

Open the site’s robots text file (robots.txt) first. Then test common paths such as /sitemap.xml and /sitemap_index.xml. Check each declared file’s response code and confirm it loads successfully. A declared sitemap can return a 404 after a domain migration, plugin change, deleted server file, incorrect redirect rule, or switch from HTTP to HTTPS.

Google accepts sitemap references in robots.txt, while google search console supports sitemap submission and monitoring. Its old sitemap ping endpoint is no longer available, as explained in Google’s sitemap ping update.

Expand sitemap index files completely

Pass: Every child sitemap in a sitemap index loads, parses, and belongs to the correct live domain.

Fail: One or more child files are missing, blocked, outdated, or overlooked, creating sitemap errors to record and resolve.

Many CMS platforms create separate files for each content type, including pages, posts, products, images, or locations. Treat each sitemap index file as a directory, not the final inventory. Record each child sitemap, its URL count, sitemap generator, and business purpose. This complete inventory feeds the later crawl analysis.

Google limits a single sitemap to 50,000 URLs or 50 MB uncompressed. If your site is smaller, an unexpectedly large sitemap should be investigated during crawl analysis, since it often points to filters, duplicate routes, or old content types that need attention. Google’s sitemap requirements outline these limits.

Check URL Eligibility and Accuracy

SEO pipeline sends canonical URLs forward while redirect, noindex, error, and blocked URLs divert away.

An XML sitemap audit starts with the same URL eligibility rules for every URL, whether it belongs to a service page, a Kolkata location page, or a B2B case study.

CheckPassFailPractical fix
Response codeReturns 200Redirect, 4xx, or 5xxRepair the page or remove it
Canonical URLPoints to the preferred URLPoints to a parameter or different pageCorrect the template rule
IndexabilityCrawlable and indexable, with no noindex directive or blocking meta robots tagRestricted from crawling or indexingRemove accidental restrictions
Internal linksLinked from relevant pagesOrphaned or deeply buriedAdd contextual links
Sitemap purposeSupports search demandThank-you, login, or test URLExclude it from the generator

Apply the same URL eligibility standard across templates, taxonomies, and CMS rules.

Test the HTTP status code before anything else

Pass: The HTTP status code must be 200, with no redirect chain.

Fail: The sitemap contains 301 redirects, 404 errors, soft 404s, server errors, or pages that time out.

A redirecting URL should be removed because the sitemap should list its final destination instead. A missing page sends Googlebot toward a dead end and makes your diagnostics noisier.

Fix errors at the source. Update internal links, correct redirect rules, restore high-value pages when appropriate, and remove retired URLs from the sitemap generator. A repeated issue across many pages usually comes from a template, taxonomy, or CMS setting.

Confirm canonical and indexability signals agree

Pass: Each listed page has the intended preferred URL, permits crawling, and can be indexed.

Fail: The sitemap lists a duplicate, a URL with a noindex directive, a robots-blocked route, or a page canonicalized elsewhere.

Sitemap inclusion is a canonical hint, so it should agree with the preferred URL you want Google to select. A lead page should return 200, use a self-referencing canonical where appropriate, and receive contextual internal links from related service or location hubs.

Exclude confirmation pages and duplicate form states. They may help users after conversion, but they don’t need to compete in organic results. Use crawl analysis to validate the final response, canonical, and indexability signals.

For sites built with React, Vue, or similar frameworks, include rendered-page checks in your JavaScript SEO audit. The source and rendered HTML can differ, including the meta robots tag, so confirm the technical SEO signals in the rendered page.

Run the XML Sitemap Audit With a Crawler

A crawler bot scans a sitemap and connected website nodes with colored status lights.

Crawl from the sitemap, then compare it with a site crawl

Pass: Sitemap URLs are crawled as one data set and compared with URLs found through internal links.

Fail: You only validate XML syntax or crawl the sitemap without checking the wider site.

In Screaming Frog SEO Spider, use sitemap mode to crawl declared URLs and export response codes, canonicals, indexability, robots directives, and titles. This crawl analysis tests the URLs Google has been asked to consider.

Next, run a normal crawl of the public website with linked XML sitemaps enabled. That crawl analysis reveals the connected URL set, including orphan URLs and pages outside the sitemap. Use the SEO Spider sitemap-mode export and the wider-site export to find old URLs, important pages without internal-link support, and other gaps.

Group errors by template and business priority

Start with URLs that generate leads, impressions, backlinks, or branded searches. A canonical problem on a profitable service page deserves faster action than a broken old campaign URL.

Group errors by content type and template, such as service pages, location pages, blog posts, or product categories. If 60 location pages carry a noindex directive, fix the sitemap generator or page template, then validate every affected URL afterward.

Review response codes separately, especially redirect chains and any redirecting URL included in the sitemap. The crawler can’t replace rendered-page checks or page-level directive validation, so confirm priority issues manually.

A lightweight Bash workflow can help on larger sites. Download the XML files, extract each <loc> URL, request headers with curl, and write status codes to a CSV. However, a script alone won’t reliably confirm rendered canonicals, page-level noindex, or internal-link depth. Use it for preliminary triage, not complete crawl analysis, then validate priority pages with SEO Spider.

Reconcile Four URL Sets to Find Indexing Gaps

Four overlapping circles show website URL relationships with a funnel and lead markers at the center.

Compare discovery and eligibility data

A strong sitemap reconciliation compares four URL sets during crawl analysis. This exposes indexation gaps and separates discovery from eligibility:

  1. URLs exported from a normal site crawl by an seo spider.
  2. URLs listed in XML sitemaps.
  3. URLs that meet url eligibility requirements because they’re canonical and indexable.
  4. URLs reported as indexed in the search engine index.

The overlap should include your most valuable pages. Orphan urls can appear in a normal site crawl but not in the sitemap. A page found internally but missing from the sitemap may lack a clear indexation policy.

Use Search Console to explain the gaps

Pass: Priority URLs appear as indexed, or your team has a documented reason for exclusion.

Fail: Important pages sit in excluded groups with no owner, fix, or follow-up date.

Use a Domain property verified through DNS, not a property controlled only by a former employee or outside agency. Domain-level visibility includes protocols and subdomains, which reduces blind spots after redesigns and URL changes.

Then use the sitemap filter in the Page Indexing report. Use crawl analysis to investigate discrepancies, and review indexation gaps individually with URL Inspection. “Crawled, currently not indexed” can point to thin content, near-duplicate location pages, weak internal linking, or unclear canonicals. The Google Search Console indexing report guide helps connect those statuses to practical fixes. After making changes, validate priority URLs with a second seo spider.

Fix the Generator and Monitor Lead Pages

Old website branches are redirected into a clean sitemap for search engine crawling.

Repair the rule, not only the individual URL

Pass: Sitemap rules automatically include only eligible canonical URLs.

Fail: Staff manually remove the same broken URL types after every publishing cycle.

Ask where the sitemap originates. It may be a WordPress plugin, Shopify app, custom CMS, headless platform, or separate marketing tool. Document who owns the sitemap generator and each inclusion rule.

For each content type, including service, location, blog, and campaign templates, set explicit inclusion rules. A location-page template should enter the sitemap only after publication, indexability, and meta robots tag checks. Its modification dates should change only after a meaningful page update. Retired campaign pages should leave the sitemap when redirects go live.

Recheck after releases and migrations

Build an xml sitemap audit into the recurring release workflow. Run a focused sitemap review after CMS updates, navigation edits, bulk content releases, URL rewrites, and site migrations. Validate modification dates after releases and migrations.

During a migration, group technical seo checks around old-to-new redirects, canonical tags, robots.txt, and the replacement sitemap before launch. Run a post-release crawl analysis with an seo spider to verify the changes.

Monitor the sitemap filter in google search console after deployment. Also watch Crawl Stats for shifts in 5xx errors, response time, and unexpected URL patterns. Crawl Stats is site-level, so use a second crawl analysis to interpret trends before investigating individual URLs with a crawler or URL Inspection.

For high-risk redesigns, follow a website migration SEO checklist and keep a change log with dates, affected templates, actions taken, and validation results.

Key Takeaways

Checklist, website graph, and lead funnel arranged in a blue SEO dashboard.

Use this short checklist during every XML sitemap audit:

  • Confirm robots.txt and Search Console point to the active sitemap files, then run an xml sitemap audit with seo spider. Review the resulting crawl analysis.
  • Expand sitemap index files and test every child sitemap.
  • Keep only 200-status, canonical URLs that respect the meta robots tag and deserve organic visibility.
  • Remove redirects, errors, parameter URLs, duplicate routes, staging pages, and noindex thank-you pages.
  • Compare sitemap data against a full crawl, Search Console, analytics, and your priority-page inventory.
  • Fix template and generator rules so the same errors don’t return.
  • Verify accurate lastmod values and review modification dates after technical releases, migrations, and large content changes.

The best sitemap is not the longest one. It is a trustworthy inventory of pages with a clear chance to generate qualified organic leads.

Frequently Asked Questions

An XML sitemap and crawler icon connect with three empty speech bubbles.

Why does Google ignore priority and changefreq?

Google ignores the priority and changefreq elements. They don’t improve rankings or force more frequent crawling. Keep modification dates accurate, reflecting meaningful page changes rather than routine sitemap regeneration.

How often should a lead-generation site run an xml sitemap audit?

Run a full review quarterly. After a migration, CMS update, navigation change, or bulk location-page release, use SEO Spider for a focused crawl analysis. If indexing, technical SEO, and lead tracking problems overlap, Get In Touch With Us for a practical review of the pages that matter most.

Keep the Sitemap Focused on Revenue Pages

A verified sitemap links a crawler to web pages and an upward path toward qualified leads.

An xml sitemap audit removes discovery and indexability barriers from valuable revenue pages. Keep service, location, industry, and conversion-supporting pages discoverable, canonical, indexable, and connected throughout the site.

A clean XML sitemap will not guarantee rankings, but it gives Google a clearer path and your team better evidence for the next fix.

Revenue Attribution for Service Businesses With Long Sales Cycles

Glowing nodes connect business touchpoints from a laptop to a contract and payment symbol.

A signed contract rarely comes from one click. For a Kolkata consulting firm, agency, IT provider, or specialist service business, a long sales cycle may take a buyer through a customer journey that starts with an SEO article, continues through an event, and includes a consultation, proposal review, and several conversations before agreement.

Revenue attribution connects those touchpoints to qualified opportunities, won deals, and eventually collected revenue. It gives marketing, sales, and finance a shared basis for deciding where to spend, without claiming that every customer journey can be measured perfectly or that attribution proves causation.

Key Takeaways: Revenue Attribution for Service Businesses

Abstract path linking five customer touchpoints to a rising revenue chart.
  • Conversion tracking records an action, such as a submitted form or booked call. Revenue attribution follows the outcome through qualification, proposal, closed-won revenue, and payment.
  • First-touch and last-touch reports are useful reference points. However, long B2B sales cycles usually need multi-touch attribution because several touchpoints influence the buyer.
  • Your CRM should hold the sales truth. It needs dependable lifecycle stages, opportunity values, close dates, service lines, and clear source fields.
  • Add advertising cost data to evaluate more than lead volume. Compare spend with qualified leads, opportunities, revenue, gross margin, and customer acquisition cost.
  • Treat attribution as decision support, not proof of causation. A channel receiving credit may have assisted a deal without being the sole reason it closed.

Why Long Sales Cycles Need More Than Lead Tracking

A winding route connects B2B sales touchpoints and ends with a contract icon.

Service purchases involve risk, comparison, and human trust. A prospect might read a case study after an organic search, receive a referral, meet your team at a trade event, then return through branded Google Ads before booking a consultation.

A basic lead report often awards the conversion to that final search or form submission. That view helps optimize a page, but it doesn’t describe the full commercial journey.

Conversion tracking and marketing attribution stop earlier

Conversion tracking answers whether someone completed a measurable action. Marketing attribution assigns credit for that action to a campaign or channel. Marketing automation can pass campaign, form, and nurture events into the CRM, but it doesn’t establish revenue by itself.

Full revenue attribution goes further. It links a lead to CRM stages such as qualified, opportunity, proposal sent, closed won, and invoice paid. Salesforce’s marketing attribution overview also stresses the value of linking multi-touch data to the sales system.

For example, a whitepaper download is not revenue. Lead attribution can identify the source of that initial contact. Revenue attribution requires later qualification, opportunity, and payment outcomes before the interaction becomes evidence of commercial impact.

Offline conversations belong in the journey

Long sales cycles contain important touchpoints that website analytics may never see. Include referral introductions, consultation calls, WhatsApp conversations, workshop attendance, proposal revisions, and sales meetings when your team can record them consistently.

Multi-touch attribution considers how several online and offline interactions may influence a long deal. AppsFlyer’s multi-touch attribution guide describes the method this way. Still, no platform can reconstruct every private conversation, device switch, or consent-limited session.

A documented unknown source is more honest than forcing every closed deal into paid search, social media, or organic traffic.

Choosing Revenue Attribution Models for Complex Deals

A central customer journey branches into five colored attribution paths.

Attribution models distribute analytical credit according to a rule. Multi-touch attribution spreads credit across recorded interactions, but it doesn’t prove that every interaction caused the deal. The best model depends on the decision you need to make, not on which report produces the most attractive return on investment.

Choose an attribution window that fits your sales cycle and data-retention limits. A window that’s too short can exclude trust-building activity from earlier stages.

First-touch, last-touch, and linear models

First-touch attribution gives full credit to the first recorded interaction. Use it to understand which channels create initial demand. It can highlight the value of SEO content, webinars, referrals, and awareness campaigns.

Last-touch attribution gives full credit to the final recorded interaction. It helps improve conversion paths, but it often favors branded search, retargeting, and direct visits that capture demand already created elsewhere.

Linear attribution divides credit equally across all recorded touchpoints. This prevents one channel from taking everything, although an initial referral and a routine email reminder may not deserve equal weight.

Keep first-touch values fixed after a person becomes known. Store later interactions separately. A clear CRM lead source naming convention prevents sales edits or automation from rewriting the origin story.

Position-based, time-decay, and account-based views

Position-based or U-shaped attribution gives extra credit to the first interaction and the lead-creation event. It works when you want to value demand creation and the moment a prospect raises their hand.

W-shaped attribution adds extra weight to the first touch, lead-creation event, and opportunity-creation event. It’s a useful heuristic, but it may not reflect each stakeholder’s actual influence in a complex service purchase.

Time-decay attribution gives more weight to recent touches. It can help evaluate late-stage proposal emails, sales calls, remarketing, and demo follow-up. However, it may undervalue content or events that built trust months earlier.

Account-based attribution groups interactions across stakeholders at one company. This suits services sold to buying committees, where a founder attends an event, a manager downloads content, and finance joins the proposal review. It requires disciplined account matching, so start with a manageable set of target accounts.

Build the Data Foundation Before Modeling

A central data hub links CRM, marketing, advertising, analytics, proposal, and finance systems.

Attribution breaks when teams use different definitions. A dependable setup joins web analytics, marketing automation, advertising platforms, the CRM, proposal software, and finance records through shared IDs and agreed rules.

Capture the handoff into sales

Use UTMs for tagged campaigns, retain click IDs where available, and match campaign cost data alongside those identifiers. Pass first-touch and latest-touch details into the CRM when a form, call, or scheduler booking creates a lead. A practical UTM governance template can help teams standardize source, medium, campaign, and naming rules.

Connect web, phone, scheduler, referral, and offline touchpoints to a stable person or account ID.

Track confirmed events, not simple button clicks or thank-you-page loads. A thank-you page can support follow-up messaging, but a validated submission event is stronger evidence that a lead exists.

GA4 can show website behavior, while the CRM should record deduplicated people, deal stages, owners, and revenue. HubSpot’s attribution report definitions describe deal-create reporting, though teams should confirm which features match their subscription and reporting setup.

Resolve identity and financial records carefully

A Customer Data Platform can consolidate consented customer identifiers from different sources. Smaller businesses may not need one immediately. A stable CRM contact or account ID, clear deduplication, and consented GA4 User-ID tracking for lead attribution often provide a practical foundation.

CPQ software also matters when pricing changes during negotiations. Map proposal amount, approved discount, service line, contract date, invoice value, and finance-validated cost data separately. The initial proposal may not match realized revenue.

For international service businesses, record the invoice currency and a documented conversion rule. Finance should own the reporting currency and treatment of refunds, credit notes, tax, commissions, and recurring retainers. A clear audit trail improves data transparency and prevents channel comparisons from mixing proposal values with revenue that was never collected.

A Practical Revenue Attribution Implementation Plan

An operations manager walks beside a five-stage roadmap with a laptop.

A useful attribution process starts small. Trying to connect every tool and every historical touchpoint at once usually creates unreliable reporting.

Define stages, fields, and ownership

Agree on the stages that matter, such as new enquiry, qualified lead, sales-qualified lead, opportunity, proposal sent, closed won, and collected revenue. Sales should own stage updates and deal values. Marketing should own campaign tagging, event definitions, and source capture. Finance should validate revenue, margin, and cost data, including channel and campaign costs.

Then establish controlled CRM dropdown values for lead source, referral type, service line, location, and loss reason. Document the source and identity rules that determine the original lead source for lead attribution. Free-text fields create duplicates such as “Linkedin,” “LinkedIn Ads,” and “LI.”

Test, reconcile, and review

Begin with a small set of high-value actions: consultation bookings, contact forms, qualified phone calls, and proposal requests. Test submissions on mobile and desktop, including cross-domain booking journeys and offline touchpoints.

Reconcile CRM leads and outcomes against GA4 events and cost data from advertising, event, content, or agency records each month. Also review whether sales pipeline progression from qualified lead to opportunity and proposal is captured consistently. Differences can come from duplicate removal, consent choices, delayed sales updates, and different attribution rules. They don’t always indicate a broken setup, but unexplained gaps need investigation.

Run first-touch, last-touch, and one multi-touch attribution view side by side for a reporting cycle. Compare conclusions before changing budget. If the data flow needs repair, Get In Touch With Us for a practical review of tracking, CRM handoffs, and reporting rules.

Turn Attribution Into Better Budget and Team Decisions

Three business leaders review channel charts on a conference room display.

Attribution should change decisions, not create a larger dashboard. Review performance across meaningful marketing channels, campaign groups, service lines, buyer types, and locations. Only compare segments with enough volume to make the results meaningful.

Bring cost data from Google Ads, LinkedIn, Meta, events, content production, and agency fees into the same view. Use standardized cost data across paid media, events, content, and agency fees. Then compare customer acquisition cost, cost per qualified lead, cost per opportunity, pipeline value, revenue per lead, and gross margin. A campaign that produces fewer enquiries may still be stronger if its deals close more often or retain longer.

Separate new business from repeat and expansion revenue. Evaluate retention and renewals through customer lifetime value, rather than comparing them directly with first-time acquisition. A client renewal email shouldn’t compete with a first-time demand-generation campaign under the same acquisition target.

Teams should also challenge suspicious findings. If retargeting receives most last-touch credit, test whether pausing or reducing spend changes qualified pipeline. Attribution identifies patterns, but controlled experiments and sales feedback help judge whether a channel created incremental demand. This supports better resource allocation across budgets and team capacity.

Revenue Attribution FAQ

A central revenue chart surrounded by four blank speech bubbles and CRM pathway shapes.

Do small service businesses need multi-touch attribution?

Yes, but the process can remain simple. Start by preserving first-touch source, latest-touch source, lead date, qualification status, opportunity value, closed revenue, and key offline interactions. A spreadsheet linked to clean CRM exports can be more useful than an expensive platform filled with incomplete data.

How should referrals be credited?

Create a referral source category and record the referring partner, client, or contact when known. Keep the referral visible alongside later marketing touches. A referred prospect may still rely on proposal content, calls, and remarketing before buying.

Can SEO revenue be measured accurately?

SEO can be connected to qualified leads and revenue when organic source data reaches the CRM. Yet search impressions, rankings, and traffic alone do not prove commercial value. Compare organic lead quality, opportunity rate, sales cycle length, and realized revenue with other channels.

Make Revenue Attribution Useful, Not Perfect

A connected B2B journey ends with a balanced revenue chart and finance summary.

Long sales cycles reward teams that preserve the complete buying path, including important touchpoints from first discovery through consultations, proposals, closed deals, and expansion revenue. Clean CRM data and stable attribution rules matter more than a complicated model.

The strongest reports make uncertainty visible while still pointing to better budget, sales, and marketing decisions. Revenue attribution earns trust when it reflects how customers actually buy.

Canonical Tag Audit for Lead Generation Websites

Website cards show duplicate URLs merging into one highlighted canonical page.
A central webpage receives organized SEO signals beside a rising search visibility chart.

A lead-generation site can lose visibility without a broken form, a bad headline, or an obvious design flaw. Incorrect canonical tags can tell Google to favor a parameter URL, an old campaign page, or thin location-page duplicate content instead of the page that should bring enquiries.

A canonical tag audit checks whether every important service, location, industry, and consultation page points to the right canonical URL. It identifies the preferred version for visibility, giving search engines a clearer indexing signal while catching hidden URLs that dilute site quality and confuse indexing reports.

What a canonical tag audit tells search engines

Duplicate URL paths converge on one highlighted canonical webpage.

A canonical tag is an HTML element in the HTML head section that identifies the URL you want search engines to treat as the preferred version. Google calls this process URL canonicalization, meaning it selects one representative URL from a group with duplicate content or very similar pages.

The tag is a strong hint, not an instruction Google must follow. Canonical tags should align with your internal links, redirects, sitemap entries, page content, and URL accessibility.

A canonical URL is not a duplicate URL

Connected website page cards show lead-generation URL groups with preferred pages highlighted.

A self referencing canonical points an indexable page to its own preferred URL. For example, a Kolkata plumbing company’s primary service page might include:

<link rel="canonical" href="https://example.com/plumbing-services-kolkata/">

That canonical URL tells Google that this exact HTTPS URL is the page owner wants indexed. In contrast, a page at https://example.com/plumbing-services-kolkata/?utm_source=google should usually canonicalize to the clean version.

Avoid vague or inconsistent targets. A canonical pointing to an HTTP URL, a URL with URL parameters, or a different city page sends mixed SEO signals.

Why lead-generation websites create duplicate groups

A board sorts service, thank-you, and tracking page cards by indexability.

Lead-gen sites often create URL variants through ad tracking, form tools, WordPress archives, campaign builders, and location-page templates. Common groups include HTTP and HTTPS versions, trailing-slash mismatches, paid-media parameters, printer pages, pagination pages, and old URLs preserved after a redesign. Pagination pages should be assessed based on whether they are unique, useful pages, rather than automatically canonicalized to page one.

Near-duplicate location pages deserve extra scrutiny. A page for Salt Lake and one for Park Street can both rank if each has useful local proof, relevant service detail, reviews, photos, and distinct FAQs. Pages that only swap the locality name may represent duplicate content and create keyword cannibalization, but genuinely distinct local pages can remain indexable.

Decide which pages deserve indexation

A business owner reviews a blurred SEO audit on one monitor in a bright office.

Start with business purpose, not the crawl total. List URLs that can produce qualified calls, quote requests, demos, and consultations. For each one, record its intended query, primary conversion, status code, indexability status, canonical URL, and internal-link count.

Service pages, industry pages, comparison pages, case studies, pricing pages, and genuinely distinct location pages often belong in Google’s index. Each should have coherent canonical tags and return a 200 status. An indexable preferred page should use a self referencing canonical, while true duplicates can point to another version.

Thank-you pages, internal search pages, login areas, duplicate form states, and test routes usually shouldn’t rank. Keep them useful for visitors when needed, but don’t let them compete with revenue pages. Decide which URL is the preferred version before making technical changes. For WordPress sites, verify the canonical output generated by Yoast SEO instead of assuming its default is correct. A broader lead generation SEO audit checklist helps connect indexability decisions with conversion and analytics checks.

A page can be technically indexable yet still be the wrong page to index. Decide its search purpose before changing its canonical.

Run a canonical tag audit in four passes

Magnifying glass over HTML source and a browser page during a canonical tag audit.

Use Screaming Frog or Sitebulb for a site audit of the public site. Export each URL’s canonical target, status code, indexability status, robots directives, crawl depth, and canonical tags. Group results by page template before reviewing individual URLs. A broken rule on a service-page template can affect hundreds of URLs.

Then compare the crawl against your intended URL inventory. Review priority pages first, especially those with impressions, organic leads, backlinks, or important internal links. On large sites, tracking variants and template-generated URLs can waste crawl budget. Canonical tags aren’t guaranteed crawl-budget controls, so they shouldn’t replace sound URL management.

Crawl declared canonicals and their targets

A preferred URL connects to four pages with different SEO error warnings.

For every canonicalized URL, test the canonical URL destination. The ideal target returns a 200 status, can be crawled, is indexable, and names itself as canonical. It shouldn’t redirect, return a 404 or 5XX error, carry noindex, or sit behind a robots.txt block.

A target becomes a non indexable canonical when it carries noindex, is blocked, or otherwise can’t serve as the indexable preferred page. Also flag pages with no canonical declaration or multiple conflicting canonical tags.

Check relative canonical values and use absolute urls that resolve consistently across protocols and hostnames. For non-HTML resources, a canonical can also appear in http headers, although this audit focuses primarily on the HTML rel="canonical" implementation. A clean self-reference is usually safer than relying on a CMS default.
A parameter page that points to its clean parent can be appropriate. For pagination pages, each useful page in the series needs an intentional canonical decision rather than an automatic page-one canonical. However, a unique pricing page that points to a generic service page may disappear from search results because Google sees a conflicting ownership signal.

Compare raw HTML, rendered HTML, and Google’s choice

Split view of HTML source and rendered DOM with matching canonical link symbols.

JavaScript frameworks can insert or rewrite canonical tags after the initial HTML response. Therefore, inspect both the server-delivered source and rendered html. A page that looks correct in a browser can still expose no canonical, or the wrong one, before scripts run.

For JavaScript-heavy sites, follow a focused JavaScript SEO audit for lead generation sites alongside the canonical review. Check that Googlebot can access the scripts and resources needed to render the final page.

Finally, inspect priority URLs in google search console. The indexed report shows both the user-declared canonical and Google’s selected canonical. Compare the final canonical in the rendered html with the page’s source implementation. Google’s URL Inspection documentation confirms that the live test can’t predict Google’s final canonical choice.

Correct canonical errors and choose the right signal

Three arrow diagrams show missing, redirected, and looping canonical targets.

Canonical problems matter most when canonical tags affect pages that should attract commercial searches. Fix the underlying page relationship, rather than adding tags blindly.
Repair broken targets, chains, and loops

Four visual paths show a clean redirect, chain, loop, and cross-domain canonical.

A canonical to a 404 page gives Google no viable target. The canonical URL should identify the preferred version, not merely a technically live page. Restore the intended page if it still has value, or update the tag to a relevant live 200 URL. Resolve 5XX responses before asking Google to reprocess the page.

A canonical chain occurs when Page A points to B, while B points to C. Change A to point directly to C when C is the real preferred page. A canonical loop occurs when A points to B and B points back to A, offering no clear answer.

Use a cross-domain canonical only when substantially duplicate content must remain available on both domains, and you deliberately want one domain’s version favored. It isn’t a shortcut for managing separate businesses, regional offers, or competing sites.
Choose canonical, redirect, noindex, or robots rules

Four SEO controls point toward one preferred webpage.
Use canonical tags when duplicate pages must remain publicly accessible, such as tracking variants or closely matched campaign pages. The HTML declaration is often called rel canonical and uses rel="canonical". 301 redirects are generally better when an old URL has no ongoing user purpose and should retire. They can consolidate signals, including link equity, while sending visitors to a replacement page.
Use noindex for pages that should remain available but don’t belong in search, including thank-you pages and private utilities. Don’t use noindex merely to force canonical selection on a duplicate page.
The robots txt file (robots.txt) controls crawling, not preferred-URL selection. Google advises against using it as a preferred-URL method because a blocked URL may still appear in search without its content. Its canonical URL guidance also describes redirects and rel="canonical" as strong signals, while sitemap inclusion is weak.

Validate fixes and prioritize by lead value

A magnifying glass reviews website status groups marked green, amber, and red.

After deployment, rerun Screaming Frog to validate canonical tags, then wait for Google to process the changes. Inspect priority URLs in google search console afterward. Start with pages that attract impressions, rank for service queries, or generate verified leads.

Prioritize a canonical error on a profitable service page above a harmless tracking URL. During redirects or migrations, consolidating link equity may help preserve signals, but it can’t guarantee ranking recovery. Check whether XML sitemaps list only indexable URLs and the final canonical URL. Remove redirects, 404s, parameters, and duplicate pagination pages from the sitemap by default. Handle useful paginated URLs deliberately.

Use the Google Search Console indexing report guide to compare crawl findings with actual exclusion patterns. If Google repeatedly chooses a different URL, review content similarity, internal linking, redirect behavior, and sitemap entries before requesting reindexing. Check for keyword cannibalization when multiple URLs rank for the same intent. A broader technical SEO review should also compare rendered html when JavaScript templates produce different canonical output.

Key takeaways and recurring audit checklist

Spreadsheet groups valuable service pages above lower-priority tracking URLs with a checklist icon.

Run this review quarterly and after migrations, CMS changes, template releases, URL rewrites, or new campaign systems:

  • Confirm every indexable money page returns 200, uses a clean canonical URL, and has canonical tags pointing to its preferred destination.
  • Check that internal navigation, XML sitemaps, and redirects support the preferred URL, while canonical tags declare it consistently.
  • Remove chains, loops, broken targets, accidental noindex rules, and canonical tags aimed at parameter URLs.
  • Inspect rendered html on JavaScript pages, rather than only server-delivered source, and compare priority URLs with the selected canonical shown in google search console.
  • Re-test form submissions and attribution after URL or redirect changes, because a technically correct repair shouldn’t break lead measurement.

Canonical checks are one part of a wider technical review. A practical technical SEO overview can help place them alongside crawlability, performance, and on-page quality.

For recurring template-level issues or unclear Search Console signals, Get In Touch With Us before more site changes create conflicting directives.

FAQ: Canonical tags on lead generation websites

Infographic showing SEO branches for canonical, redirect, noindex, and indexable pages.

Why does Google ignore my canonical tag? Google, like other search engines, may select another URL when signals conflict across redirects, internal links, sitemaps, content similarity, or accessibility. Review Google’s canonicalization troubleshooting guidance before changing multiple signals at once.

Do all pages need canonical tags? Every page you want indexed should generally declare a clean canonical URL that references itself. Pages that are true duplicates should point to the page that owns the content instead.

Can a canonical replace a 301 redirect? No. A rel="canonical" declaration is a hint, not a replacement for a redirect. Use a 301 when the old URL should no longer serve visitors. Use a canonical when both similar URLs must stay accessible.

Clean canonicals protect the pages that generate leads

Four panels illustrate redirects, noindex, internal links, and an XML sitemap.

Canonical tags help search engines identify one representative destination for each meaningful page group. For a service or location page, that destination is the canonical URL, the preferred version eligible to represent the group.

They also keep service and location pages from competing with outdated campaigns, tracked variants, and duplicate content.

The goal isn’t a perfect audit score. It’s clear indexing signals for the pages most likely to turn searches into qualified conversations.